Q8UEM4
Gene name |
nrdJ (Atu1733, AGR_C_3183) |
Protein name |
Vitamin B12-dependent ribonucleotide reductase |
Names |
Ribonucleoside-diphosphate reductase NrdJ |
Species |
Agrobacterium fabrum (strain C58 / ATCC 33970) (Agrobacterium tumefaciens (strain C58)) |
KEGG Pathway |
atu:Atu1733 |
EC number |
1.17.4.1: With a disulfide as acceptor |
Protein Class |
|
Descriptions
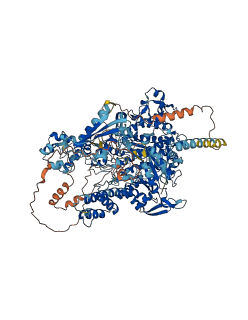
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
1 structures for Q8UEM4
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| AF-Q8UEM4-F1 | Predicted | AlphaFoldDB |
No variants for Q8UEM4
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
| No variants for Q8UEM4 | |||||
No associated diseases with Q8UEM4
3 regional properties for Q8UEM4
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| domain | Ribonucleotide reductase large subunit, C-terminal | 198 - 749 | IPR000788-1 |
| domain | Ribonucleotide reductase large subunit, C-terminal | 810 - 913 | IPR000788-2 |
| domain | Ribonucleotide reductase class II vitamin B12-dependent, N-terminal domain | 31 - 147 | IPR013678 |
Functions
| Description | ||
|---|---|---|
| EC Number | 1.17.4.1 | With a disulfide as acceptor |
| Subcellular Localization |
|
|
| PANTHER Family | ||
| PANTHER Subfamily | ||
| PANTHER Protein Class | ||
| PANTHER Pathway Category | No pathway information available | |
No GO annotations of cellular component
| Name | Definition |
|---|---|
| No GO annotations for cellular component |
4 GO annotations of molecular function
| Name | Definition |
|---|---|
| cobalamin binding | Binding to cobalamin (vitamin B12), a water-soluble vitamin characterized by possession of a corrin nucleus containing a cobalt atom. |
| cobalt ion binding | Binding to a cobalt ion (Co). |
| nucleotide binding | Binding to a nucleotide, any compound consisting of a nucleoside that is esterified with (ortho)phosphate or an oligophosphate at any hydroxyl group on the ribose or deoxyribose. |
| ribonucleoside-diphosphate reductase activity, thioredoxin disulfide as acceptor | Catalysis of the reaction: 2'-deoxyribonucleoside diphosphate + thioredoxin disulfide + H2O = ribonucleoside diphosphate + thioredoxin. Thioredoxin disulfide is the oxidized form of thioredoxin. |
2 GO annotations of biological process
| Name | Definition |
|---|---|
| DNA biosynthetic process | The biosynthetic process resulting in the formation of DNA. |
| DNA replication | The cellular metabolic process in which a cell duplicates one or more molecules of DNA. DNA replication begins when specific sequences, known as origins of replication, are recognized and bound by initiation proteins, and ends when the original DNA molecule has been completely duplicated and the copies topologically separated. The unit of replication usually corresponds to the genome of the cell, an organelle, or a virus. The template for replication can either be an existing DNA molecule or RNA. |
No homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| No homologous proteins | ||||
| 10 | 20 | 30 | 40 | 50 | 60 |
| MRIERRFTKP | GQSSYAEIEF | RKAVSEIKNP | DGSVVFRLAD | IDVPAQFSQV | ATDVLAQKYF |
| 70 | 80 | 90 | 100 | 110 | 120 |
| RKAGVPKLLK | KVEENDVPSF | LWRSVADEKA | LKELPEAERY | GSETDARQVF | DRLAGTWAYW |
| 130 | 140 | 150 | 160 | 170 | 180 |
| GWKGKYFSTE | EDASAFKDEL | AYMLATQRVA | PNSPQWFNTG | LHWAYGIDGP | GQGHFYVDPF |
| 190 | 200 | 210 | 220 | 230 | 240 |
| TGKLTKSKSA | YEHPQPHACF | IQSVEDDLVN | EGGIMDLWVR | EARLFKYGSG | TGSNFSYLRG |
| 250 | 260 | 270 | 280 | 290 | 300 |
| EGEKLSGGGK | SSGLMSFLKI | GDRAAGAIKS | GGTTRRAAKM | VVVDADHPDI | EAYIDWKVNE |
| 310 | 320 | 330 | 340 | 350 | 360 |
| EQKVAALVTG | SKIVAKHLKA | IMKACVNCEA | DNGDCFDPAK | NPALKREIRA | AKKDMVPENY |
| 370 | 380 | 390 | 400 | 410 | 420 |
| VKRVIQFAEQ | GYKDIQFKTY | DTDWDSEAYL | TVSGQNSNNS | VSLKDDFLRA | VENDGNWNLT |
| 430 | 440 | 450 | 460 | 470 | 480 |
| ARKDGKVMKT | LKARDLWEKI | SHAAWASADP | GLHFNTTMND | WHTSPAEGPI | RASNPCSEYM |
| 490 | 500 | 510 | 520 | 530 | 540 |
| FLDDTACNLA | SLNLLQFKDA | KTKRIDIADY | EHAVRLWTVV | LEVSVMMAQF | PSRQIAERSY |
| 550 | 560 | 570 | 580 | 590 | 600 |
| EYRTLGLGYA | NIGGLLMSSG | IPYDSDEGRA | IAGALTAIMT | GVSYATSAEM | AGELGPFPSF |
| 610 | 620 | 630 | 640 | 650 | 660 |
| APNRDNMLRV | IRNHRRAAHG | QSEGYEGLSV | NPVALIHADC | TDQDLVAHAT | AAWDKALELG |
| 670 | 680 | 690 | 700 | 710 | 720 |
| EKHGYRNAQT | TVIAPTGTIG | LVMDCDTTGI | EPDFALVKFK | KLAGGGYFKI | INRAVPESLR |
| 730 | 740 | 750 | 760 | 770 | 780 |
| SLGYSESQIA | EIEAYAVGHG | NLNQAPAINP | STLKAKGFTD | EKIEAVNAAL | KSAFDIKFVF |
| 790 | 800 | 810 | 820 | 830 | 840 |
| NQWTLGADFL | KGTLKVSDEQ | LSDMSFNLLD | HLGFAKKDIE | AANVHVCGAM | TLEGAPFLKN |
| 850 | 860 | 870 | 880 | 890 | 900 |
| EHLAVFDCAN | PCGKIGKRYL | SVESHIRMMA | AAQPFISGAI | SKTINMPNDA | TVEDCGAAYM |
| 910 | 920 | 930 | 940 | 950 | 960 |
| LSWKLALKAN | ALYRDGSKLS | QPLNASLVED | EDDEDFVEEL | IQQPLAQQAV | TITEKIVERV |
| 970 | 980 | 990 | 1000 | 1010 | 1020 |
| IERVSREREK | LPNRRQGYTQ | KATVGGHKVY | LRTGEFGDGR | IGEIFIDMHK | EGAAFRAMMN |
| 1030 | 1040 | 1050 | 1060 | 1070 | 1080 |
| NFAIAISLGL | QYGVPLEEYV | EAFTFTKFEP | AGMVQGNDAI | KNATSILDYV | FRELAVSYLG |
| 1090 | 1100 | 1110 | 1120 | 1130 | 1140 |
| RHDLAHVDTS | DFSNTALGKG | IQEGKTNLLS | TGWTRGYKPT | LVSSNEGDRA | ASEPKGSATA |
| 1150 | 1160 | 1170 | 1180 | 1190 | 1200 |
| APARGSANVT | SFAGSAARKL | EPTVAITTSE | IVSFKRDYEE | RAKELAEEIA | EEVIDEVVQE |
| 1210 | 1220 | 1230 | 1240 | 1250 | 1260 |
| AQQTATALFS | DKAAADAASA | KAEAKKKENE | RRMRSIAQGY | TGNMCSECQN | FTMVRNGTCE |
| 1270 | |||||
| KCDTCGATSG | CS |