Q8RWY4
Gene name |
NLP6 (At1g64530, F1N19.10) |
Protein name |
Protein NLP6 |
Names |
AtNLP6, NIN-like protein 6, Nodule inception protein-like protein 6 |
Species |
Arabidopsis thaliana (Mouse-ear cress) |
KEGG Pathway |
ath:AT1G64530 |
EC number |
|
Protein Class |
|
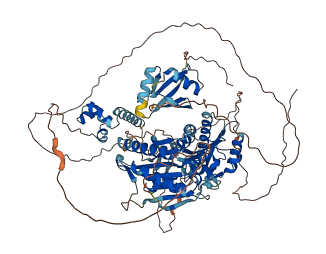
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
1 structures for Q8RWY4
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| AF-Q8RWY4-F1 | Predicted | AlphaFoldDB |
103 variants for Q8RWY4
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
| ENSVATH00120536 | 9 | S>C | No | 1000Genomes | |
| ENSVATH00120537 | 19 | F>C | No | 1000Genomes | |
| ENSVATH13722823 | 20 | A>P | No | 1000Genomes | |
| tmp_1_23959914_C_A | 32 | S>Y | No | 1000Genomes | |
| ENSVATH01462165 | 45 | T>A | No | 1000Genomes | |
| tmp_1_23959959_G_C | 47 | G>A | No | 1000Genomes | |
| ENSVATH00120538 | 52 | E>D | No | 1000Genomes | |
| ENSVATH14409994 | 53 | L>I | No | 1000Genomes | |
| ENSVATH13722824 | 55 | S>P | No | 1000Genomes | |
| ENSVATH05058490 | 60 | P>S | No | 1000Genomes | |
| tmp_1_23960004_G_T | 62 | R>L | No | 1000Genomes | |
| ENSVATH14410015 | 87 | S>F | No | 1000Genomes | |
| ENSVATH13722827 | 88 | P>L | No | 1000Genomes | |
| ENSVATH01462166 | 92 | I>V | No | 1000Genomes | |
| ENSVATH05058497 | 96 | E>D | No | 1000Genomes | |
| tmp_1_23960376_G_A | 132 | V>I | No | 1000Genomes | |
| ENSVATH05058505 | 232 | V>L | No | 1000Genomes | |
| ENSVATH00120547 | 272 | T>P | No | 1000Genomes | |
| tmp_1_23960888_C_G | 272 | T>S | No | 1000Genomes | |
| ENSVATH14410016 | 312 | R>H | No | 1000Genomes | |
| ENSVATH13722832 | 326 | S>L | No | 1000Genomes | |
| tmp_1_23961253_A_G | 351 | H>R | No | 1000Genomes | |
| tmp_1_23961327_C_G | 376 | Q>E | No | 1000Genomes | |
| tmp_1_23961364_G_A | 388 | R>Q | No | 1000Genomes | |
| ENSVATH01462170 | 393 | D>N | No | 1000Genomes | |
| ENSVATH14410017 | 394 | Y>H | No | 1000Genomes | |
| tmp_1_23961447_A_T | 416 | T>S | No | 1000Genomes | |
| tmp_1_23961450_T_C | 417 | Y>H | No | 1000Genomes | |
| ENSVATH14410018 | 455 | S>L | No | 1000Genomes | |
| ENSVATH13722833 | 461 | S>Y | No | 1000Genomes | |
| tmp_1_23961630_G_C | 477 | A>P | No | 1000Genomes | |
| ENSVATH01462171 | 478 | S>L | No | 1000Genomes | |
| ENSVATH05058535 | 481 | G>R | No | 1000Genomes | |
| ENSVATH00120557 | 482 | M>I | No | 1000Genomes | |
| ENSVATH13722834 | 491 | R>W | No | 1000Genomes | |
| ENSVATH05058537 | 492 | I>V | No | 1000Genomes | |
| ENSVATH05058538 | 497 | Q>P | No | 1000Genomes | |
| ENSVATH14410019 | 501 | D>E | No | 1000Genomes | |
| tmp_1_23961728_A_C | 509 | E>D | No | 1000Genomes | |
| ENSVATH13722835 | 509 | E>K | No | 1000Genomes | |
| ENSVATH05058539 | 512 | V>L | No | 1000Genomes | |
| ENSVATH05058539 | 512 | V>M | No | 1000Genomes | |
| ENSVATH13722836 | 515 | N>K | No | 1000Genomes | |
| tmp_1_23961747_T_C | 516 | S>P | No | 1000Genomes | |
| ENSVATH05058540 | 518 | F>L | No | 1000Genomes | |
| ENSVATH05058541 | 523 | E>D | No | 1000Genomes | |
| tmp_1_23961775_A_C | 525 | D>A | No | 1000Genomes | |
| ENSVATH05058542 | 527 | G>R | No | 1000Genomes | |
| ENSVATH05058543 | 528 | V>F | No | 1000Genomes | |
| ENSVATH05058544 | 530 | R>K | No | 1000Genomes | |
| ENSVATH01462173 | 531 | F>V | No | 1000Genomes | |
| ENSVATH05058545 | 534 | L>V | No | 1000Genomes | |
| ENSVATH13722837 | 537 | I>T | No | 1000Genomes | |
| tmp_1_23961813_C_T | 538 | P>S | No | 1000Genomes | |
| tmp_1_23961819_G_A | 540 | A>T | No | 1000Genomes | |
| ENSVATH05058547 | 540 | A>V | No | 1000Genomes | |
| ENSVATH14410020 | 546 | S>P | No | 1000Genomes | |
| ENSVATH05058548 | 567 | A>S | No | 1000Genomes | |
| tmp_1_23962050_G_A | 592 | G>R | No | 1000Genomes | |
| ENSVATH13722840 | 620 | G>D | No | 1000Genomes | |
| ENSVATH14410022 | 634 | P>A | No | 1000Genomes | |
| tmp_1_23962187_C_G | 637 | H>Q | No | 1000Genomes | |
| tmp_1_23962189_A_G | 638 | Q>R | No | 1000Genomes | |
| ENSVATH05058563 | 639 | I>M | No | 1000Genomes | |
| ENSVATH05058565 | 641 | P>L | No | 1000Genomes | |
| ENSVATH05058564 | 641 | P>S | No | 1000Genomes | |
| ENSVATH05058566 | 643 | D>A | No | 1000Genomes | |
| ENSVATH05058567 | 643 | D>E | No | 1000Genomes | |
| ENSVATH05058568 | 644 | I>N | No | 1000Genomes | |
| ENSVATH05058569 | 647 | A>P | No | 1000Genomes | |
| tmp_1_23962227_C_T | 651 | P>S | No | 1000Genomes | |
| tmp_1_23962231_C_T | 652 | P>L | No | 1000Genomes | |
| tmp_1_23962233_A_T | 653 | T>S | No | 1000Genomes | |
| tmp_1_23962245_C_T | 657 | P>S | No | 1000Genomes | |
| ENSVATH05058572 | 662 | Q>K | No | 1000Genomes | |
| tmp_1_23962272_A_C | 666 | I>L | No | 1000Genomes | |
| ENSVATH05058573 | 669 | R>K | No | 1000Genomes | |
| tmp_1_23962293_G_A | 673 | D>N | No | 1000Genomes | |
| tmp_1_23962311_A_G | 679 | T>A | No | 1000Genomes | |
| ENSVATH05058574 | 681 | R>C | No | 1000Genomes | |
| ENSVATH05058575 | 681 | R>H | No | 1000Genomes | |
| ENSVATH01462175 | 682 | A>G | No | 1000Genomes | |
| ENSVATH05058579 | 687 | N>D | No | 1000Genomes | |
| ENSVATH05058580 | 687 | N>S | No | 1000Genomes | |
| ENSVATH13722844 | 688 | P>L | No | 1000Genomes | |
| ENSVATH05058581 | 690 | C>S | No | 1000Genomes | |
| tmp_1_23962447_C_T | 693 | R>C | No | 1000Genomes | |
| tmp_1_23962448_G_T | 693 | R>L | No | 1000Genomes | |
| tmp_1_23962457_T_A | 696 | L>H | No | 1000Genomes | |
| ENSVATH05058582 | 700 | N>K | No | 1000Genomes | |
| ENSVATH05058583 | 707 | V>A | No | 1000Genomes | |
| tmp_1_23962532_A_G | 721 | N>S | No | 1000Genomes | |
| tmp_1_23962537_T_A | 723 | W>R | No | 1000Genomes | |
| ENSVATH05058585 | 727 | T>S | No | 1000Genomes | |
| tmp_1_23962561_A_T | 731 | T>S | No | 1000Genomes | |
| tmp_1_23962574_C_T | 735 | T>I | No | 1000Genomes | |
| ENSVATH05058588 | 757 | I>L | No | 1000Genomes | |
| ENSVATH14410046 | 758 | S>L | No | 1000Genomes | |
| tmp_1_23962654_G_A | 762 | V>I | No | 1000Genomes | |
| ENSVATH05058590 | 765 | T>A | No | 1000Genomes | |
| tmp_1_23962709_C_A | 780 | A>E | No | 1000Genomes | |
| ENSVATH13722847 | 825 | F>L | No | 1000Genomes | |
| ENSVATH13722848 | 840 | C>S | No | 1000Genomes |
No associated diseases with Q8RWY4
1 GO annotations of cellular component
| Name | Definition |
|---|---|
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
2 GO annotations of molecular function
| Name | Definition |
|---|---|
| DNA-binding transcription factor activity | A transcription regulator activity that modulates transcription of gene sets via selective and non-covalent binding to a specific double-stranded genomic DNA sequence (sometimes referred to as a motif) within a cis-regulatory region. Regulatory regions include promoters (proximal and distal) and enhancers. Genes are transcriptional units, and include bacterial operons. |
| transcription cis-regulatory region binding | Binding to a specific sequence of DNA that is part of a regulatory region that controls transcription of that section of the DNA. The transcribed region might be described as a gene, cistron, or operon. |
No GO annotations of biological process
| Name | Definition |
|---|---|
| No GO annotations for biological process |
No homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| No homologous proteins | ||||
| 10 | 20 | 30 | 40 | 50 | 60 |
| MELDDLDLSG | SWPLDQITFA | SNFKSPVIFS | SSEQPFSPLW | SFSETSGDVG | GELYSAAVAP |
| 70 | 80 | 90 | 100 | 110 | 120 |
| TRFTDYSVLL | ASSESETTTK | ENNQVPSPSW | GIMPLENPDS | YCAIKAKMTQ | ALRYFKESTG |
| 130 | 140 | 150 | 160 | 170 | 180 |
| QQHVLAQVWA | PVKNRGRYVL | TTSGQPFVLG | PNSNGLNQYR | MVSLTYMFSL | DGERDGELGL |
| 190 | 200 | 210 | 220 | 230 | 240 |
| PGRVFRKKLP | EWTPNVQYYS | SKEFSRLGHA | LHYNVQGTLA | LPVFEPSRQL | CVGVVELIMT |
| 250 | 260 | 270 | 280 | 290 | 300 |
| SPKINYAPEV | EKVCKALEAV | NLKTSEILNH | ETTQICNEGR | QNALAEILEI | LTVVCETYKL |
| 310 | 320 | 330 | 340 | 350 | 360 |
| PLAQTWVPCR | HRSVLAFGGG | FKKSCSSFDG | SCMGKVCMST | SDLAVYVVDA | HVWGFRDACA |
| 370 | 380 | 390 | 400 | 410 | 420 |
| EHHLQKGQGV | AGRAFQSGNL | CFCRDVTRFC | KTDYPLVHYA | RMFKLTSCFA | VCLKSTYTGD |
| 430 | 440 | 450 | 460 | 470 | 480 |
| DEYVLEFFLP | PAITDKSEQD | CLLGSLLQTM | KQHYSSLKVV | SETELCENNM | SLEVVEASED |
| 490 | 500 | 510 | 520 | 530 | 540 |
| GMVYSKLEPI | RIHHPAQISK | DYLELNAPEQ | KVSLNSDFME | NNEVDDGVER | FQTLDPIPEA |
| 550 | 560 | 570 | 580 | 590 | 600 |
| KTVKKSERKR | GKTEKTISLE | VLQQYFAGSL | KDAAKSLGVC | PTTMKRICRQ | HGISRWPSRK |
| 610 | 620 | 630 | 640 | 650 | 660 |
| INKVNRSLTR | LKHVIDSVQG | ADGSLNLTSL | SPRPWPHQIP | PIDIQLAKNC | PPTSTSPLSN |
| 670 | 680 | 690 | 700 | 710 | 720 |
| LQDVKIENRD | AEDSAGSSTS | RASCKVNPIC | ETRFRLPTHN | QEPSRQVALD | DSDSSSKNMT |
| 730 | 740 | 750 | 760 | 770 | 780 |
| NFWAHLTCQD | TASPTILQHK | LVSIKATYRE | DIIRFKISPE | SVSITELKQQ | VAKRLKLETA |
| 790 | 800 | 810 | 820 | 830 | 840 |
| AFELKYLDDD | REWVSVSCDA | DLSECLDTSA | AKANTLRLSV | HDVTFNFGSS | CESSEETMMC |
| L |