Q6Q151
Gene name |
CYP59 (At1g53720, F22G10.24) |
Protein name |
Peptidyl-prolyl cis-trans isomerase CYP59 |
Names |
AtCYP59, PPIase CYP59, Cyclophilin-59 |
Species |
Arabidopsis thaliana (Mouse-ear cress) |
KEGG Pathway |
ath:AT1G53720 |
EC number |
5.2.1.8: Cis-trans isomerases |
Protein Class |
|
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
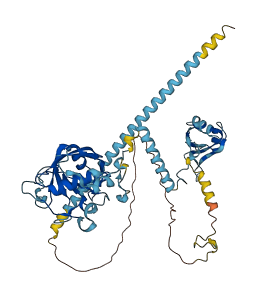
1 structures for Q6Q151
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| AF-Q6Q151-F1 | Predicted | AlphaFoldDB |
39 variants for Q6Q151
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
| ENSVATH00096562 | 6 | V>M | No | 1000Genomes | |
| tmp_1_20057207_A_T | 36 | Y>F | No | 1000Genomes | |
| tmp_1_20057227_C_T | 43 | H>Y | No | 1000Genomes | |
| tmp_1_20057270_C_T | 57 | T>I | No | 1000Genomes | |
| ENSVATH00096564 | 78 | Y>F | No | 1000Genomes | |
| ENSVATH13560460 | 87 | K>E | No | 1000Genomes | |
| tmp_1_20057557_T_C | 96 | M>T | No | 1000Genomes | |
| tmp_1_20057569_G_A | 100 | G>E | No | 1000Genomes | |
| ENSVATH04955844 | 105 | A>G | No | 1000Genomes | |
| ENSVATH04955845 | 115 | D>N | No | 1000Genomes | |
| tmp_1_20057751_C_G | 124 | T>S | No | 1000Genomes | |
| tmp_1_20057903_C_T | 146 | P>L | No | 1000Genomes | |
| tmp_1_20057935_A_C | 157 | K>Q | No | 1000Genomes | |
| tmp_1_20057987_A_G | 174 | E>G | No | 1000Genomes | |
| ENSVATH00096565 | 176 | M>I | No | 1000Genomes | |
| tmp_1_20058025_G_A | 187 | E>K | No | 1000Genomes | |
| ENSVATH13560482 | 190 | K>I | No | 1000Genomes | |
| tmp_1_20058037_G_A | 191 | D>N | No | 1000Genomes | |
| ENSVATH13560483 | 217 | E>A | No | 1000Genomes | |
| tmp_1_20058295_A_G | 249 | K>R | No | 1000Genomes | |
| ENSVATH01366931 | 271 | S>L | No | 1000Genomes | |
| ENSVATH04955856 | 333 | D>G | No | 1000Genomes | |
| ENSVATH13560499 | 333 | D>Y | No | 1000Genomes | |
| ENSVATH04955857 | 336 | K>N | No | 1000Genomes | |
| tmp_1_20059039_T_C | 351 | I>T | No | 1000Genomes | |
| ENSVATH13560501 | 352 | A>G | No | 1000Genomes | |
| ENSVATH04955864 | 379 | E>D | No | 1000Genomes | |
| tmp_1_20059138_G_T | 384 | G>V | No | 1000Genomes | |
| ENSVATH00096568 | 397 | R>T | No | 1000Genomes | |
| ENSVATH04955865 | 417 | Q>L | No | 1000Genomes | |
| ENSVATH04955867 | 433 | D>G | No | 1000Genomes | |
| ENSVATH04955868 | 442 | R>T | No | 1000Genomes | |
| tmp_1_20059331_G_C | 448 | E>D | No | 1000Genomes | |
| tmp_1_20059335_A_T | 450 | R>W | No | 1000Genomes | |
| tmp_1_20059347_G_A | 454 | D>N | No | 1000Genomes | |
| ENSVATH13560502 | 473 | R>S | No | 1000Genomes | |
| tmp_1_20059420_A_G | 478 | H>R | No | 1000Genomes | |
| tmp_1_20059455_G_A | 490 | E>K | No | 1000Genomes | |
| ENSVATH00096569 | 504 | R>K | No | 1000Genomes |
No associated diseases with Q6Q151
4 regional properties for Q6Q151
Functions
| Description | ||
|---|---|---|
| EC Number | 5.2.1.8 | Cis-trans isomerases |
| Subcellular Localization |
|
|
| PANTHER Family | ||
| PANTHER Subfamily | ||
| PANTHER Protein Class | ||
| PANTHER Pathway Category | No pathway information available | |
1 GO annotations of cellular component
| Name | Definition |
|---|---|
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
3 GO annotations of molecular function
| Name | Definition |
|---|---|
| peptidyl-prolyl cis-trans isomerase activity | Catalysis of the reaction: peptidyl-proline (omega=180) = peptidyl-proline (omega=0). |
| RNA binding | Binding to an RNA molecule or a portion thereof. |
| zinc ion binding | Binding to a zinc ion (Zn). |
2 GO annotations of biological process
| Name | Definition |
|---|---|
| protein peptidyl-prolyl isomerization | The modification of a protein by cis-trans isomerization of a proline residue. |
| regulation of phosphorylation of RNA polymerase II C-terminal domain | Any process that modulates the frequency, rate or extent of phosphorylation of RNA polymerase II C-terminal domain. |
No homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| No homologous proteins | ||||
| 10 | 20 | 30 | 40 | 50 | 60 |
| MSVLIVTSLG | DIVIDLHSDK | CPLTCKNFLK | LCKIKYYNGC | LFHTVQKDFT | AQTGDPTGTG |
| 70 | 80 | 90 | 100 | 110 | 120 |
| AGGDSIYKFL | YGEQARFYKD | EIHLDLKHSK | TGTVAMASGG | ENLNASQFYF | TLRDDLDYLD |
| 130 | 140 | 150 | 160 | 170 | 180 |
| GKHTVFGQIA | EGFDTLTRIN | EAYVDPKNRP | YKNIRIKHTH | ILDDPFDDPP | QLAEMMPDAS |
| 190 | 200 | 210 | 220 | 230 | 240 |
| PEGKPKEEVK | DDVRLEDDWV | PMDEELGAQE | LEEVIREKAA | HSSAVVLESI | GDIPEAEVKP |
| 250 | 260 | 270 | 280 | 290 | 300 |
| PDNVLFVCKL | NPVTEDEDLH | TIFSRFGTVV | SADVIRDFKT | GDSLCYAFIE | FENKESCEQA |
| 310 | 320 | 330 | 340 | 350 | 360 |
| YFKMDNALID | DRRIHVDFSQ | SVSKLWSQFR | QKDSQKGKGN | GCFKCGSTDH | IAKDCVGGPS |
| 370 | 380 | 390 | 400 | 410 | 420 |
| SKFIVKDQNR | QHGGGEGYEM | VFEGDVHETP | KHNSHERERS | EKIQRRSPHG | NGEGKRQHRD |
| 430 | 440 | 450 | 460 | 470 | 480 |
| ERDDGRRQHD | REDARELERK | HRERKERESR | EDEDRRRRRR | REESRDKESR | RERDEDDHRS |
| 490 | 500 | ||||
| HRDYKERRRE | RDDRHGREAR | HERRDR |