Q6FPQ3
Gene name |
MPH1 |
Protein name |
ATP-dependent DNA helicase MPH1 |
Names |
FANCM-like protein 1 |
Species |
Candida glabrata (strain ATCC 2001 / CBS 138 / JCM 3761 / NBRC 0622 / NRRL Y-65) (Yeast) (Torulopsis glabrata) |
KEGG Pathway |
cgr:CAGL0J01980g |
EC number |
3.6.4.12: Acting on ATP; involved in cellular and subcellular movement |
Protein Class |
|
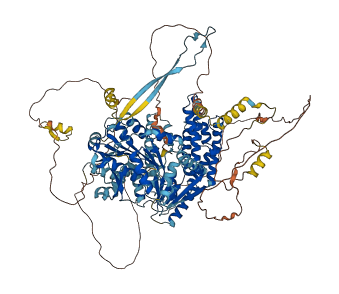
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
1 structures for Q6FPQ3
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| AF-Q6FPQ3-F1 | Predicted | AlphaFoldDB |
No variants for Q6FPQ3
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
| No variants for Q6FPQ3 | |||||
No associated diseases with Q6FPQ3
5 regional properties for Q6FPQ3
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| domain | Helicase, C-terminal | 432 - 649 | IPR001650 |
| domain | Helicase/UvrB, N-terminal | 82 - 239 | IPR006935 |
| domain | Helicase superfamily 1/2, ATP-binding domain | 78 - 278 | IPR014001 |
| domain | FANCM/Mph1-like, insert domain | 290 - 407 | IPR039686 |
| domain | FANCM, DEAH-box helicase domain | 80 - 260 | IPR044749 |
Functions
| Description | ||
|---|---|---|
| EC Number | 3.6.4.12 | Acting on ATP; involved in cellular and subcellular movement |
| Subcellular Localization |
|
|
| PANTHER Family | ||
| PANTHER Subfamily | ||
| PANTHER Protein Class | ||
| PANTHER Pathway Category | No pathway information available | |
2 GO annotations of cellular component
| Name | Definition |
|---|---|
| chromosome, telomeric region | The end of a linear chromosome, required for the integrity and maintenance of the end. A chromosome telomere usually includes a region of telomerase-encoded repeats the length of which rarely exceeds 20 bp each and that permits the formation of a telomeric loop (T-loop). The telomeric repeat region is usually preceded by a sub-telomeric region that is gene-poor but rich in repetitive elements. Some telomeres only consist of the latter part (for eg. D. melanogaster telomeres). |
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
5 GO annotations of molecular function
| Name | Definition |
|---|---|
| 3'-5' DNA helicase activity | Unwinding a DNA helix in the direction 5' to 3', driven by ATP hydrolysis. |
| ATP binding | Binding to ATP, adenosine 5'-triphosphate, a universally important coenzyme and enzyme regulator. |
| ATP hydrolysis activity | Catalysis of the reaction: ATP + H2O = ADP + H+ phosphate. ATP hydrolysis is used in some reactions as an energy source, for example to catalyze a reaction or drive transport against a concentration gradient. |
| DNA/RNA helicase activity | Unwinding of a DNA/RNA duplex, i.e. a double helix in which a strand of DNA pairs with a complementary strand of RNA, driven by ATP hydrolysis. |
| flap-structured DNA binding | Binding to a flap structure in DNA. A DNA flap structure is one in which a single-stranded length of DNA or RNA protrudes from a double-stranded DNA molecule. |
5 GO annotations of biological process
| Name | Definition |
|---|---|
| DNA replication, Okazaki fragment processing | The DNA metabolic process, occurring during lagging strand synthesis, by which RNA primers are removed from Okazaki fragments, the resulting gaps filled by DNA polymerization, and the ends ligated to form a continuous strand. |
| donor selection | The process that determines which donor locus a cell uses, in preference to another, in mating type switching. |
| interstrand cross-link repair | Removal of a DNA interstrand crosslink (a covalent attachment of DNA bases on opposite strands of the DNA) and restoration of the DNA. DNA interstrand crosslinks occur when both strands of duplex DNA are covalently tethered together (e.g. by an exogenous or endogenous agent), thus preventing the strand unwinding necessary for essential DNA functions such as transcription and replication. |
| negative regulation of strand invasion | Any process that decreases the rate, frequency or extent of strand invasion. Strand invasion is the process in which the nucleoprotein complex (composed of the broken single-strand DNA and the recombinase) searches and identifies a region of homology in intact duplex DNA. The broken single-strand DNA displaces the like strand and forms Watson-Crick base pairs with its complement, forming a duplex in which each strand is from one of the two recombining DNA molecules. |
| recombinational repair | A DNA repair process that involves the exchange, reciprocal or nonreciprocal, of genetic material between the broken DNA molecule and a homologous DNA region. |
No homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| No homologous proteins | ||||
| 10 | 20 | 30 | 40 | 50 | 60 |
| MEDSDFDDAE | LDELYEKAIN | RRVNETLIRR | SLPVQRDLQN | GVVPGQDTYY | EEIRTEVTFG |
| 70 | 80 | 90 | 100 | 110 | 120 |
| PTHHQLNEEL | LHSYIYPTNF | EVRDYQFDIV | RKGLLQNILC | AIPTGMGKTF | IASTVMLNFF |
| 130 | 140 | 150 | 160 | 170 | 180 |
| RWTKTAKIIF | TAPTRPLVAQ | QIKACLGITG | IPHDQTAILL | DKTRKNREEI | WANKRVFFTT |
| 190 | 200 | 210 | 220 | 230 | 240 |
| PQVVENDLKR | GVLNPKDIVC | LVIDEAHRAT | GSYAYANLVK | FINRFNSSYR | LLALTATPAT |
| 250 | 260 | 270 | 280 | 290 | 300 |
| DIEGVQEVVN | NLNISKIEIR | TEESMDIVKY | MKKKIKDRVN | IQTTVEIENI | VEQLGIAILP |
| 310 | 320 | 330 | 340 | 350 | 360 |
| VLNQAVELGI | YESCPPSAIN | AFKAMQKSQA | IIMNPSIPEG | IKWRNYFILQ | LLNHVGQMLK |
| 370 | 380 | 390 | 400 | 410 | 420 |
| RIKIYGIRTF | FSYFQNKVKE | FTTKYDLGKS | TNKIAAGFYY | HPMIQAITKE | CEEKIKDPNF |
| 430 | 440 | 450 | 460 | 470 | 480 |
| LGHGKLEHLR | DELTQFFYEN | PFESRVIIFT | ELRESALEIV | KCIDSMENSE | IRPHIFIGQA |
| 490 | 500 | 510 | 520 | 530 | 540 |
| KGKEGFDEVK | FVRKHGPKGR | KKSDREKRLE | EERRMDEEKK | QAALQEKLER | TSRRTGSSEE |
| 550 | 560 | 570 | 580 | 590 | 600 |
| AQLSGMNQKQ | QKEVIKKFKS | GLYNVLVCTS | IGEEGLDIGE | VDLIICYDTT | SSPIKNIQRM |
| 610 | 620 | 630 | 640 | 650 | 660 |
| GRTGRKRDGR | IVLMFSSNEA | SKFDQSMNDY | YNLQKLISQH | LVQYRKSDRI | LPPENQEPEC |
| 670 | 680 | 690 | 700 | 710 | 720 |
| EKKFIEVSEE | DQELNNMEDT | DDVIRFATQC | MLGKIPKTKK | GRDKGKAKKG | KTFFMPDNVI |
| 730 | 740 | 750 | 760 | 770 | 780 |
| TGIITANNLV | RKRKSAQNGS | GAALLDSIVN | DDIDLEDEDG | QVEILDVDQE | VNRRLASNAV |
| 790 | 800 | 810 | 820 | 830 | 840 |
| QKTNDMALQI | RNEETPEIGD | TRNKAKASSS | MKVKKEPTMA | VDHSDDEEDL | PLSRHVERAS |
| 850 | 860 | 870 | 880 | 890 | 900 |
| RETAKEVPNA | TNVAEKPFPP | LEFGVQRPSK | RQRLQPEVQP | EVQPEVQPEV | QPEVQPEVQP |
| 910 | 920 | 930 | 940 | 950 | 960 |
| EVTVKPEVKI | KTEEGSKLYK | NIFFSDEGFL | QPHEKELFLS | KYNPEDATVT | IEPVPRFVRA |
| 970 | 980 | 990 | 1000 | 1010 | 1020 |
| HGRVKHSKRT | EQLITLFEDM | NHNRVARTIE | MNKLRGIARR | LHTVSQSQGQ | SNSQSQAHST |
| 1030 | 1040 | 1050 | |||
| SQKSQQASQK | DRSSQDKDLT | NSELEDLLDS | DF |