Q24JK4
Gene name |
XRCC1 |
Protein name |
DNA-repair protein XRCC1 |
Names |
AtXRCC1, Homolog of X-ray repair cross complementing 1 |
Species |
Arabidopsis thaliana (Mouse-ear cress) |
KEGG Pathway |
ath:AT1G80420 |
EC number |
|
Protein Class |
|
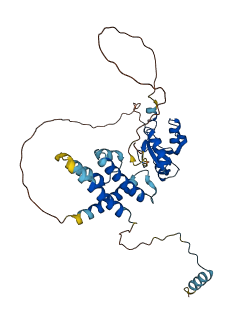
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
1 structures for Q24JK4
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| AF-Q24JK4-F1 | Predicted | AlphaFoldDB |
21 variants for Q24JK4
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
| tmp_1_30237083_C_A | 27 | K>N | No | 1000Genomes | |
| ENSVATH05179290 | 35 | E>K | No | 1000Genomes | |
| ENSVATH05179289 | 36 | E>D | No | 1000Genomes | |
| tmp_1_30236983_T_C | 61 | K>E | No | 1000Genomes | |
| ENSVATH13844113 | 73 | F>V | No | 1000Genomes | |
| tmp_1_30236816_G_A | 83 | S>L | No | 1000Genomes | |
| tmp_1_30236811_C_T | 85 | A>T | No | 1000Genomes | |
| tmp_1_30236769_C_T | 99 | G>S | No | 1000Genomes | |
| tmp_1_30236686_C_A | 126 | K>N | No | 1000Genomes | |
| tmp_1_30236505_T_C | 157 | S>G | No | 1000Genomes | |
| ENSVATH13844108 | 181 | T>K | No | 1000Genomes | |
| ENSVATH00800239 | 205 | F>S | No | 1000Genomes | |
| tmp_1_30236053_G_A | 220 | T>I | No | 1000Genomes | |
| tmp_1_30236054_T_A | 220 | T>S | No | 1000Genomes | |
| tmp_1_30235935_G_A | 233 | P>L | No | 1000Genomes | |
| tmp_1_30235932_C_G | 234 | G>A | No | 1000Genomes | |
| ENSVATH13844103 | 254 | S>F | No | 1000Genomes | |
| ENSVATH05179282 | 269 | S>C | No | 1000Genomes | |
| tmp_1_30235664_A_G | 281 | M>T | No | 1000Genomes | |
| tmp_1_30235450_A_T | 352 | C>* | No | 1000Genomes | |
| ENSVATH14496391 | 352 | C>Y | No | 1000Genomes |
No associated diseases with Q24JK4
1 GO annotations of cellular component
| Name | Definition |
|---|---|
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
2 GO annotations of molecular function
| Name | Definition |
|---|---|
| damaged DNA binding | Binding to damaged DNA. |
| double-stranded methylated DNA binding | Binding to double-stranded methylated DNA. Methylation of cytosine or adenine in DNA is an important mechanism for establishing stable heritable epigenetic marks. |
7 GO annotations of biological process
| Name | Definition |
|---|---|
| base-excision repair | In base excision repair, an altered base is removed by a DNA glycosylase enzyme, followed by excision of the resulting sugar phosphate. The small gap left in the DNA helix is filled in by the sequential action of DNA polymerase and DNA ligase. |
| DNA demethylation | The removal of a methyl group from one or more nucleotides within an DNA molecule. |
| DNA ligation | The re-formation of a broken phosphodiester bond in the DNA backbone, carried out by DNA ligase. |
| double-strand break repair via nonhomologous end joining | The repair of a double-strand break in DNA in which the two broken ends are rejoined with little or no sequence complementarity. Information at the DNA ends may be lost due to the modification of broken DNA ends. This term covers instances of separate pathways, called classical (or canonical) and alternative nonhomologous end joining (C-NHEJ and A-NHEJ). These in turn may further branch into sub-pathways, but evidence is still unclear. |
| positive regulation of DNA-5-methylcytosine glycosylase activity | Any process that activates or increases the frequency, rate or extent of DNA-5-methylcytosine glycosylase activity. |
| positive regulation of polynucleotide 3'-phosphatase activity | Any process that activates or increases the frequency, rate or extent of polynucleotide 3'-phosphatase activity. |
| single strand break repair | The repair of single strand breaks in DNA. Repair of such breaks is mediated by the same enzyme systems as are used in base excision repair. |
No homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| No homologous proteins | ||||
| 10 | 20 | 30 | 40 | 50 | 60 |
| MSQKRNLPSW | MSSRDPEITP | SKSHCKKPKD | EGPTEEHNSR | NAPSNKSEHA | EPSSNTTEFS |
| 70 | 80 | 90 | 100 | 110 | 120 |
| KLMEGVVFVL | SGFVNPERST | LRSQALTMGA | TYQPDWNAGS | TLLICAFPNT | PKFRQVETNG |
| 130 | 140 | 150 | 160 | 170 | 180 |
| GTIISKEWIT | ECYAQKKLVD | IEQYLMHAGK | PWRKSSSPQD | ANREKREHLS | KKPEKQVEKK |
| 190 | 200 | 210 | 220 | 230 | 240 |
| TETRGTPSTS | SKNRSACNLV | KEPFFVTEVK | KWARDDLSQT | ISWLESQEEK | PEPGEIKRIA |
| 250 | 260 | 270 | 280 | 290 | 300 |
| AEGVLTCLQD | AIDSLEQKQD | IGSVTELWSF | VPRVVKELGK | MESSSKKENS | TASKEEVCKQ |
| 310 | 320 | 330 | 340 | 350 | |
| AKSWKKIYEA | ELAKPGEDES | TSRVACGYDS | DMTVEMTEEE | IELAYRNVSL | ECL |