P52655
Gene name |
GTF2A1 (TF2A1) |
Protein name |
Transcription initiation factor IIA subunit 1 |
Names |
General transcription factor IIA subunit 1, TFIIAL, Transcription initiation factor TFIIA 42 kDa subunit, TFIIA-42 |
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:2957 |
EC number |
|
Protein Class |
|
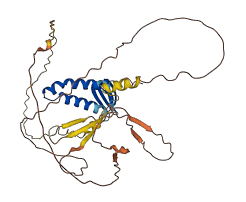
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
50 structures for P52655
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| 1NVP | X-ray | 210 A | PDB | ||
| 5FUR | EM | 850 A | PDB | ||
| 5IY6 | EM | 720 A | N | 1-376 | PDB |
| 5IY7 | EM | 860 A | N | 1-376 | PDB |
| 5IY8 | EM | 790 A | N | 1-376 | PDB |
| 5IY9 | EM | 630 A | N | 1-376 | PDB |
| 5IYA | EM | 540 A | N | 1-376 | PDB |
| 5IYB | EM | 390 A | N | 1-376 | PDB |
| 5IYC | EM | 390 A | N | 1-376 | PDB |
| 5IYD | EM | 390 A | N | 1-376 | PDB |
| 5M4S | X-ray | 238 A | PDB | ||
| 6MZM | EM | 750 A | W | 9-376 | PDB |
| 6O9L | EM | 720 A | N | 1-376 | PDB |
| 7EDX | EM | 450 A | Q | 1-376 | PDB |
| 7EG7 | EM | 620 A | Q | 1-376 | PDB |
| 7EG8 | EM | 740 A | Q | 1-376 | PDB |
| 7EG9 | EM | 370 A | Q | 1-376 | PDB |
| 7EGA | EM | 410 A | Q | 1-376 | PDB |
| 7EGB | EM | 330 A | Q | 1-376 | PDB |
| 7EGC | EM | 390 A | Q | 1-376 | PDB |
| 7EGD | EM | 675 A | Q | 1-376 | PDB |
| 7EGI | EM | 982 A | Q | 1-376 | PDB |
| 7EGJ | EM | 864 A | Q | 1-376 | PDB |
| 7LBM | EM | 480 A | M | 1-376 | PDB |
| 7NVR | EM | 450 A | U | 1-376 | PDB |
| 7NVS | EM | 280 A | U | 1-376 | PDB |
| 7NVT | EM | 290 A | U | 1-376 | PDB |
| 7NVU | EM | 250 A | U | 1-376 | PDB |
| 7NVY | EM | 730 A | U | 1-376 | PDB |
| 7NVZ | EM | 720 A | U | 1-376 | PDB |
| 7NW0 | EM | 660 A | U | 1-376 | PDB |
| 7ZWC | EM | 320 A | U | 1-376 | PDB |
| 7ZWD | EM | 300 A | U | 1-376 | PDB |
| 7ZX7 | EM | 340 A | U | 1-376 | PDB |
| 7ZX8 | EM | 300 A | U | 1-376 | PDB |
| 7ZXE | EM | 350 A | U | 1-376 | PDB |
| 8BVW | EM | 400 A | U | 1-376 | PDB |
| 8BYQ | EM | 410 A | U | 1-376 | PDB |
| 8BZ1 | EM | 380 A | U | 1-376 | PDB |
| 8GXQ | EM | 504 A | DQ | 1-376 | PDB |
| 8GXS | EM | 416 A | DQ | 1-376 | PDB |
| 8WAK | EM | 547 A | Q | 1-376 | PDB |
| 8WAL | EM | 852 A | Q | 1-376 | PDB |
| 8WAN | EM | 607 A | Q | 1-376 | PDB |
| 8WAO | EM | 640 A | Q | 1-376 | PDB |
| 8WAP | EM | 585 A | Q | 1-376 | PDB |
| 8WAQ | EM | 629 A | Q | 1-376 | PDB |
| 8WAR | EM | 720 A | Q | 1-376 | PDB |
| 8WAS | EM | 613 A | Q | 1-376 | PDB |
| AF-P52655-F1 | Predicted | AlphaFoldDB |
201 variants for P52655
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
CA390733500 rs1595236795 |
3 | N>T | No |
ClinGen Ensembl |
|
|
CA390733495 rs1350403861 |
4 | S>A | No |
ClinGen TOPMed gnomAD |
|
| TCGA novel | 4 | S>L | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA390733488 rs1455032542 |
5 | A>G | No |
ClinGen gnomAD |
|
|
CA7294952 rs751806247 |
5 | A>T | No |
ClinGen ExAC gnomAD |
|
|
rs763824221 CA7294951 |
6 | N>D | No |
ClinGen ExAC gnomAD |
|
|
CA390733486 rs763824221 |
6 | N>H | No |
ClinGen ExAC gnomAD |
|
|
TCGA novel rs200315855 CA263958337 |
6 | N>K | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen 1000Genomes gnomAD NCI-TCGA |
|
CA390733474 rs1595236757 |
8 | N>H | No |
ClinGen Ensembl |
|
|
rs1595236753 CA390733471 |
8 | N>T | No |
ClinGen Ensembl |
|
|
CA390733466 rs1595236747 |
9 | T>P | No |
ClinGen Ensembl |
|
|
rs1161031071 CA390733460 |
10 | V>M | No |
ClinGen gnomAD |
|
|
CA390733435 rs1309045242 |
12 | K>E | No |
ClinGen gnomAD |
|
| TCGA novel | 12 | K>Q | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1407628114 CA390733432 |
12 | K>R | No |
ClinGen TOPMed |
|
|
CA390733416 rs1293283722 |
14 | Y>C | No |
ClinGen TOPMed gnomAD |
|
|
CA390733410 rs1449603493 |
15 | R>T | No |
ClinGen gnomAD |
|
|
rs1420999911 CA390733405 |
16 | S>P | No |
ClinGen gnomAD |
|
|
CA390733399 rs1184448825 |
17 | V>L | No |
ClinGen gnomAD |
|
|
rs760524289 CA7294925 |
20 | D>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA390733355 rs1326970667 |
23 | N>S | No |
ClinGen TOPMed |
|
|
CA390733342 rs1229253759 |
25 | V>L | No |
ClinGen TOPMed |
|
| VAR_035667 | 30 | L>V | a breast cancer sample; somatic mutation [UniProt] | No | UniProt |
|
CA390733279 rs1490005106 |
34 | V>L | No |
ClinGen gnomAD |
|
|
CA390733247 rs1383523091 |
38 | V>E | No |
ClinGen gnomAD |
|
|
CA390733243 rs1309372821 |
39 | L>V | No |
ClinGen gnomAD |
|
|
CA7294923 rs200289434 |
40 | M>K | No |
ClinGen 1000Genomes ExAC gnomAD |
|
| TCGA novel | 41 | E>K | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1317136431 CA390733215 |
43 | K>T | No |
ClinGen TOPMed |
|
|
CA390733205 rs1595232932 |
44 | T>S | No |
ClinGen Ensembl |
|
| TCGA novel | 47 | E>K | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 48 | N>H | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1393345568 CA390732050 |
48 | N>S | No |
ClinGen TOPMed gnomAD |
|
| TCGA novel | 48 | N>T | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs754745611 CA7294879 |
51 | M>T | No |
ClinGen ExAC gnomAD |
|
|
COSM197050 CA390732001 rs1444155041 |
55 | A>T | large_intestine [Cosmic] | No |
ClinGen cosmic curated gnomAD |
|
CA390731987 rs1195660576 |
57 | D>V | No |
ClinGen gnomAD |
|
|
rs1489300777 CA390731967 |
60 | H>Y | No |
ClinGen TOPMed |
|
|
CA7294877 rs779698902 |
61 | S>L | No |
ClinGen ExAC gnomAD |
|
|
rs755584424 CA7294876 |
62 | E>V | No |
ClinGen ExAC gnomAD |
|
|
rs1189279846 CA390731945 |
63 | E>G | No |
ClinGen TOPMed |
|
|
CA390731902 rs1355098841 |
69 | Q>H | No |
ClinGen gnomAD |
|
|
rs1220120090 CA390731906 |
69 | Q>P | No |
ClinGen gnomAD |
|
|
CA390731894 rs1270222060 |
71 | Q>E | No |
ClinGen gnomAD |
|
|
CA7294874 rs746616919 |
71 | Q>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1414265441 CA390731859 |
75 | Q>H | No |
ClinGen TOPMed |
|
|
rs200868697 CA263944562 |
75 | Q>K | No |
ClinGen 1000Genomes |
|
|
CA7294870 rs759857062 |
76 | P>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA390731844 rs1301877483 |
78 | Q>K | No |
ClinGen gnomAD |
|
|
CA390731841 rs1424555510 |
78 | Q>R | No |
ClinGen gnomAD |
|
|
CA263944529 rs979794325 |
82 | H>Q | No |
ClinGen TOPMed gnomAD |
|
|
CA263944509 rs201567417 |
83 | H>Q | No |
ClinGen Ensembl |
|
|
CA263944520 rs201983978 |
83 | H>Y | No |
ClinGen 1000Genomes |
|
|
rs1326386458 CA390731779 |
86 | H>R | No |
ClinGen TOPMed |
|
|
rs1460675118 CA390731781 |
86 | H>Y | No |
ClinGen TOPMed gnomAD |
|
|
CA390731767 rs1310388030 |
87 | H>Q | No |
ClinGen Ensembl |
|
|
CA390731769 rs1372784951 |
87 | H>R | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed gnomAD |
|
CA263944494 rs76069174 |
88 | Q>* | No |
ClinGen Ensembl |
|
|
CA7294864 rs760695064 |
89 | Q>R | No |
ClinGen ExAC gnomAD |
|
|
CA7294862 rs772748894 |
91 | Q>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs748662198 CA7294861 |
93 | Q>E | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA7294860 rs779479018 |
95 | T>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA390731698 rs1196969592 |
98 | Q>* | No |
ClinGen gnomAD |
|
|
rs1336863695 CA390731685 |
99 | Q>H | No |
ClinGen TOPMed gnomAD |
|
|
CA263944443 rs552611415 |
100 | A>S | No |
ClinGen 1000Genomes |
|
|
COSM1209155 rs768916940 CA7294859 |
100 | A>V | large_intestine [Cosmic] | No |
ClinGen cosmic curated ExAC gnomAD |
|
rs779604498 CA7294857 |
101 | Q>P | No |
ClinGen ExAC gnomAD |
|
|
CA390731653 rs1414689257 |
104 | Q>H | No |
ClinGen TOPMed |
|
|
CA390731651 rs1407547285 |
105 | V>I | No |
ClinGen TOPMed |
|
|
rs1281716549 CA390731635 |
107 | I>T | No |
ClinGen gnomAD |
|
|
VAR_054043 rs17111579 CA263944419 |
109 | A>P | No |
ClinGen UniProt TOPMed dbSNP |
|
|
CA390731626 rs17111579 |
109 | A>T | No |
ClinGen TOPMed |
|
|
CA7294855 rs749949255 |
110 | S>T | No |
ClinGen ExAC gnomAD |
|
|
CA7294854 rs780648477 |
111 | Q>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs751481940 CA7294852 |
113 | A>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA7294799 rs199739518 |
120 | V>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1292857056 CA390731357 |
123 | S>C | No |
ClinGen gnomAD |
|
|
rs1480605566 CA390731334 |
126 | I>M | No |
ClinGen gnomAD |
|
|
CA390731339 rs1355738554 |
126 | I>V | No |
ClinGen gnomAD |
|
|
rs1168154350 CA390731325 |
128 | H>N | No |
ClinGen gnomAD |
|
|
CA7294797 rs770615006 |
128 | H>R | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 131 | A>T | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA7294796 rs138294263 |
133 | N>T | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs1178940900 CA390731281 |
134 | M>V | No |
ClinGen gnomAD |
|
|
CA390731259 rs1178036906 |
135 | S>G | No |
ClinGen gnomAD |
|
|
rs1445303604 CA390731256 |
135 | S>T | No |
ClinGen gnomAD |
|
|
rs1280431791 CA390731205 |
143 | L>F | No |
ClinGen TOPMed |
|
|
rs760009596 CA7294780 |
143 | L>I | No |
ClinGen ExAC gnomAD |
|
|
rs1318578922 CA390731183 |
147 | A>E | No |
ClinGen gnomAD |
|
|
CA390731155 rs1306469145 |
151 | P>S | No |
ClinGen gnomAD |
|
|
rs1238864494 CA390731140 |
153 | Q>K | No |
ClinGen gnomAD |
|
|
rs1373911003 CA390730953 |
162 | L>V | No |
ClinGen gnomAD |
|
|
rs1595216572 CA390730924 |
164 | Q>R | No |
ClinGen Ensembl |
|
|
CA390730915 rs1362666235 |
165 | V>L | No |
ClinGen TOPMed |
|
|
rs1433691806 CA390730889 |
167 | R>S | No |
ClinGen TOPMed |
|
|
CA390730886 rs1595216555 |
168 | A>P | No |
ClinGen Ensembl |
|
|
rs778963555 CA7294763 |
168 | A>V | No |
ClinGen ExAC gnomAD |
|
|
rs1274939746 CA390730879 |
169 | A>T | No |
ClinGen TOPMed |
|
|
rs147948047 CA7294762 |
170 | N>S | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA390730847 rs1566855578 |
171 | G>D | No |
ClinGen Ensembl |
|
|
CA390730840 rs1217436419 |
172 | A>S | No |
ClinGen TOPMed |
|
|
CA7294761 rs754359577 |
174 | Y>C | No |
ClinGen ExAC gnomAD |
|
|
rs1490475041 CA390730811 |
175 | I>F | No |
ClinGen gnomAD |
|
|
CA263937110 rs936687867 |
176 | F>L | No |
ClinGen Ensembl |
|
|
rs1329578672 CA390730792 |
177 | Q>H | No |
ClinGen TOPMed |
|
|
CA390730779 rs1210402735 |
179 | Q>H | No |
ClinGen TOPMed |
|
|
CA7294759 rs756534940 |
183 | V>F | No |
ClinGen ExAC gnomAD |
|
|
rs535983219 CA263937040 |
189 | I>L | No |
ClinGen 1000Genomes |
|
|
CA390730698 rs1247373412 |
191 | Q>H | No |
ClinGen TOPMed |
|
|
rs1479269711 CA390730686 |
193 | Q>* | No |
ClinGen TOPMed |
|
|
CA390730681 rs1316468939 |
193 | Q>H | No |
ClinGen gnomAD |
|
|
CA390730678 rs1277918352 |
194 | P>S | No |
ClinGen gnomAD |
|
|
rs1406094085 CA390730663 |
196 | G>V | No |
ClinGen gnomAD |
|
|
rs1347871827 CA390730661 |
197 | V>I | No |
ClinGen gnomAD |
|
|
CA263937030 rs920017522 |
199 | A>G | No |
ClinGen TOPMed |
|
|
rs1397261123 CA390730641 |
200 | P>S | No |
ClinGen gnomAD |
|
|
CA390730631 rs1169895027 |
202 | I>L | No |
ClinGen gnomAD |
|
|
rs775569470 CA7294752 |
202 | I>M | No |
ClinGen ExAC gnomAD |
|
|
rs762492938 CA7294753 |
202 | I>R | No |
ClinGen ExAC gnomAD |
|
|
rs769812325 CA7294751 |
203 | Q>R | No |
ClinGen ExAC |
|
|
rs972848028 CA263937008 |
204 | Q>R | No |
ClinGen TOPMed |
|
|
rs900503612 CA263933697 |
207 | A>T | No |
ClinGen TOPMed |
|
|
CA263933671 rs151035780 |
208 | P>A | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA7294733 rs151035780 |
208 | P>S | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs759390225 CA7294732 |
209 | L>V | No |
ClinGen ExAC gnomAD |
|
|
rs776551423 CA7294731 |
215 | P>A | No |
ClinGen ExAC gnomAD |
|
|
rs770648110 CA7294730 |
217 | T>A | No |
ClinGen ExAC gnomAD |
|
|
rs1296182876 CA390730491 |
223 | P>A | No |
ClinGen gnomAD |
|
|
CA390730481 rs1444026902 |
224 | Q>R | No |
ClinGen TOPMed |
|
|
CA7294727 rs569178593 |
225 | Q>H | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
| TCGA novel | 225 | Q>P | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1379826598 CA390730456 |
228 | F>L | No |
ClinGen TOPMed |
|
|
CA390730434 rs1238148117 |
231 | N>S | No |
ClinGen gnomAD |
|
| TCGA novel | 234 | Q>D | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1320932199 CA390730397 |
236 | I>M | No |
ClinGen TOPMed |
|
|
CA7294724 rs756709499 |
236 | I>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs780077444 CA7294725 |
236 | I>V | No |
ClinGen ExAC gnomAD |
|
|
rs1242741904 CA390730395 |
237 | P>A | No |
ClinGen Ensembl |
|
|
CA390730392 rs1232874185 |
237 | P>R | No |
ClinGen TOPMed |
|
|
CA390730390 rs1360714051 |
238 | T>A | No |
ClinGen gnomAD |
|
|
rs781681151 CA7294723 |
238 | T>M | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
|
CA7294722 rs781681151 |
238 | T>R | No |
ClinGen ExAC gnomAD |
|
|
rs757566499 CA7294721 |
239 | T>A | No |
ClinGen ExAC gnomAD |
|
|
rs751929090 CA7294720 |
241 | A>V | No |
ClinGen ExAC gnomAD |
|
|
CA7294719 rs142893489 |
242 | A>P | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA7294718 rs758097664 |
243 | P>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA7294717 rs752292521 |
244 | T>A | No |
ClinGen ExAC gnomAD |
|
|
rs550854086 CA7294716 |
246 | A>S | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA7294715 rs550854086 |
246 | A>T | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA7294714 rs535458284 |
246 | A>V | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs1288832212 CA390730341 |
247 | Q>P | No |
ClinGen gnomAD |
|
|
rs199532026 CA263933499 |
249 | Q>R | No |
ClinGen TOPMed gnomAD |
|
|
CA390730286 rs1292538699 |
250 | I>K | No |
ClinGen gnomAD |
|
|
CA7294713 rs148530628 |
250 | I>V | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1230242604 CA390730241 |
253 | T>A | No |
ClinGen gnomAD |
|
|
rs1377175956 CA390730231 |
253 | T>I | No |
ClinGen gnomAD |
|
|
CA390730147 rs1283804846 |
258 | P>L | No |
ClinGen gnomAD |
|
| TCGA novel | 259 | Q>L | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA7294711 rs772971756 |
259 | Q>R | No |
ClinGen ExAC gnomAD |
|
|
rs768907982 CA7294710 |
260 | A>V | No |
ClinGen ExAC gnomAD |
|
|
rs1398014754 CA390730101 |
261 | Q>K | No |
ClinGen gnomAD |
|
|
CA390730084 rs1423656476 |
262 | P>S | No |
ClinGen TOPMed |
|
|
rs1359357429 CA390729986 |
266 | Q>R | No |
ClinGen gnomAD |
|
|
rs934514610 CA263933456 |
271 | L>S | No |
ClinGen TOPMed |
|
|
CA7294707 rs769776748 |
276 | T>I | No |
ClinGen ExAC gnomAD |
|
|
CA7294706 rs374094911 |
279 | T>A | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ESP ExAC NCI-TCGA TOPMed gnomAD |
|
rs781578392 CA7294705 |
280 | S>L | No |
ClinGen ExAC gnomAD |
|
|
CA263933423 rs928338825 |
282 | E>D | No |
ClinGen Ensembl |
|
|
CA7294704 rs771415588 |
282 | E>Q | No |
ClinGen ExAC gnomAD |
|
|
CA390729654 rs1169373346 |
286 | D>E | No |
ClinGen TOPMed |
|
|
rs747425299 CA7294702 |
289 | E>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1319995088 CA390729554 |
293 | D>G | No |
ClinGen gnomAD |
|
|
CA7294697 rs754481422 CA7294696 |
294 | D>E | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1215359958 CA390729540 |
294 | D>G | No |
ClinGen TOPMed gnomAD |
|
|
rs752413471 CA7294699 |
294 | D>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA390729546 rs752413471 |
294 | D>N | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs752413471 CA7294698 |
294 | D>Y | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs200502995 CA7294695 |
295 | E>D | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs887820232 CA263933350 |
299 | K>Q | No |
ClinGen TOPMed gnomAD |
|
|
CA390729435 rs1566853922 |
302 | D>E | No |
ClinGen Ensembl |
|
|
rs766276254 CA7294694 |
302 | D>V | No |
ClinGen ExAC |
|
|
rs745748481 CA263933319 |
302 | D>Y | No |
ClinGen Ensembl |
|
|
rs760576204 CA7294693 |
304 | A>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1424570272 CA390727277 |
327 | E>D | No |
ClinGen gnomAD |
|
|
rs1438666622 CA390727178 |
332 | E>D | No |
ClinGen gnomAD |
|
|
CA263926766 rs958495523 |
333 | N>S | No |
ClinGen Ensembl |
|
|
CA390726119 rs1299371432 |
346 | K>I | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
CA390726106 rs1358712108 |
348 | K>* | No |
ClinGen gnomAD |
|
| TCGA novel | 349 | W>* | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 352 | H>R | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA7294645 rs755210057 |
353 | L>F | No |
ClinGen ExAC |
|
|
rs867553569 CA263922581 |
356 | G>V | No |
ClinGen Ensembl |
|
| TCGA novel | 358 | M>I | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs766672017 CA7294643 |
361 | N>S | No |
ClinGen ExAC gnomAD |
|
|
CA390726001 rs1260058499 |
362 | G>E | No |
ClinGen TOPMed |
|
|
rs1421883806 CA390725967 |
367 | F>L | No |
ClinGen gnomAD |
|
|
rs1256481522 CA390725955 |
368 | S>F | No |
ClinGen gnomAD |
|
|
CA7294641 rs200244214 |
371 | I>T | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA390725934 rs1357025118 |
372 | G>R | No |
ClinGen TOPMed |
|
|
CA390725920 rs1211380717 |
374 | A>T | No |
ClinGen TOPMed |
|
| TCGA novel | 376 | W>* | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
No associated diseases with P52655
No regional properties for P52655
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| No domain, repeats, and functional sites for P52655 | |||
6 GO annotations of cellular component
| Name | Definition |
|---|---|
| cytosol | The part of the cytoplasm that does not contain organelles but which does contain other particulate matter, such as protein complexes. |
| nucleoplasm | That part of the nuclear content other than the chromosomes or the nucleolus. |
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
| transcription factor TFIIA complex | A component of the transcription machinery of RNA Polymerase II. In humans, TFIIA is a heterotrimer composed of an alpha (P35), beta (P19) and gamma subunits (P12). |
| transcription factor TFIID complex | A complex composed of TATA binding protein (TBP) and TBP associated factors (TAFs); the total mass is typically about 800 kDa. Most of the TAFs are conserved across species. In TATA-containing promoters for RNA polymerase II (Pol II), TFIID is believed to recognize at least two distinct elements, the TATA element and a downstream promoter element. TFIID is also involved in recognition of TATA-less Pol II promoters. Binding of TFIID to DNA is necessary but not sufficient for transcription initiation from most RNA polymerase II promoters. |
| transcription preinitiation complex | A protein-DNA complex composed of proteins binding promoter DNA to form the transcriptional preinitiation complex (PIC), the formation of which is a prerequisite for transcription. |
7 GO annotations of molecular function
| Name | Definition |
|---|---|
| DNA binding | Any molecular function by which a gene product interacts selectively and non-covalently with DNA (deoxyribonucleic acid). |
| protein heterodimerization activity | Binding to a nonidentical protein to form a heterodimer. |
| RNA polymerase II core promoter sequence-specific DNA binding | Binding to a DNA sequence that is part of the core promoter of a RNA polymerase II-transcribed gene. |
| RNA polymerase II general transcription initiation factor activity | A general transcription initiation factor activity that contributes to transcription start site selection and transcription initiation of genes transcribed by RNA polymerase II. The general transcription factors for RNA polymerase II include TFIIB, TFIID, TFIIE, TFIIF, TFIIH and TATA-binding protein (TBP). In most species, RNA polymerase II transcribes all messenger RNAs (mRNAs), most untranslated regulatory RNAs, the majority of the snoRNAs, four of the five snRNAs (U1, U2, U4, and U5), and other small noncoding RNAs. For some small RNAs there is variability between species as to whether it is transcribed by RNA polymerase II or RNA polymerase III. However there are also rare exceptions, such as Trypanosoma brucei, where RNA polymerase I transcribes certain mRNAs in addition to its normal role in rRNA transcription. |
| RNA polymerase II general transcription initiation factor binding | Binding to a basal RNA polymerase II transcription factor, any of the factors involved in formation of the preinitiation complex (PIC) by RNA polymerase II and defined as a basal or general transcription factor. |
| RNA polymerase II-specific DNA-binding transcription factor binding | Binding to a sequence-specific DNA binding RNA polymerase II transcription factor, any of the factors that interact selectively and non-covalently with a specific DNA sequence in order to modulate transcription. |
| TBP-class protein binding | Binding to a member of the class of TATA-binding proteins (TBP), including any of the TBP-related factors (TRFs). |
4 GO annotations of biological process
| Name | Definition |
|---|---|
| positive regulation of transcription by RNA polymerase II | Any process that activates or increases the frequency, rate or extent of transcription from an RNA polymerase II promoter. |
| positive regulation of transcription initiation by RNA polymerase II | Any process that increases the rate, frequency or extent of a process involved in starting transcription from an RNA polymerase II promoter. |
| RNA polymerase II preinitiation complex assembly | The aggregation, arrangement and bonding together of proteins on an RNA polymerase II promoter DNA to form the transcriptional preinitiation complex (PIC), the formation of which is a prerequisite for transcription by RNA polymerase. |
| transcription by RNA polymerase II | The synthesis of RNA from a DNA template by RNA polymerase II (RNAP II), originating at an RNA polymerase II promoter. Includes transcription of messenger RNA (mRNA) and certain small nuclear RNAs (snRNAs). |
No homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| No homologous proteins | ||||
| 10 | 20 | 30 | 40 | 50 | 60 |
| MANSANTNTV | PKLYRSVIED | VINDVRDIFL | DDGVDEQVLM | ELKTLWENKL | MQSRAVDGFH |
| 70 | 80 | 90 | 100 | 110 | 120 |
| SEEQQLLLQV | QQQHQPQQQQ | HHHHHHHQQA | QPQQTVPQQA | QTQQVLIPAS | QQATAPQVIV |
| 130 | 140 | 150 | 160 | 170 | 180 |
| PDSKLIQHMN | ASNMSAAATA | ATLALPAGVT | PVQQILTNSG | QLLQVVRAAN | GAQYIFQPQQ |
| 190 | 200 | 210 | 220 | 230 | 240 |
| SVVLQQQVIP | QMQPGGVQAP | VIQQVLAPLP | GGISPQTGVI | IQPQQILFTG | NKTQVIPTTV |
| 250 | 260 | 270 | 280 | 290 | 300 |
| AAPTPAQAQI | TATGQQQPQA | QPAQTQAPLV | LQVDGTGDTS | SEEDEDEEED | YDDDEEEDKE |
| 310 | 320 | 330 | 340 | 350 | 360 |
| KDGAEDGQVE | EEPLNSEDDV | SDEEGQELFD | TENVVVCQYD | KIHRSKNKWK | FHLKDGIMNL |
| 370 | |||||
| NGRDYIFSKA | IGDAEW |