O60921
Gene name |
HUS1 |
Protein name |
Checkpoint protein HUS1 |
Names |
hHUS1 |
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:3364 |
EC number |
|
Protein Class |
|
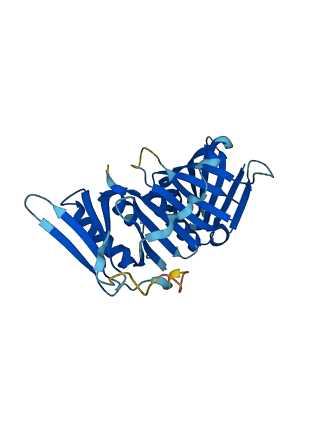
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
8 structures for O60921
243 variants for O60921
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
CA158098520 rs565968847 |
4 | R>Q | No |
ClinGen 1000Genomes TOPMed gnomAD |
|
|
CA4254838 rs138248432 |
4 | R>W | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs929255655 CA158098514 |
5 | A>T | No |
ClinGen TOPMed |
|
|
rs1290243825 CA367478240 |
6 | K>E | No |
ClinGen gnomAD |
|
|
rs2307255 CA158098513 |
7 | I>V | No |
ClinGen TOPMed gnomAD |
|
|
rs1296244296 CA367478161 |
8 | V>M | No |
ClinGen TOPMed gnomAD |
|
|
rs762826065 CA4254834 |
9 | D>E | No |
ClinGen ExAC gnomAD |
|
|
CA367478137 rs1467385363 |
9 | D>N | No |
ClinGen gnomAD |
|
|
rs202090804 CA367478102 CA367478097 |
10 | G>R | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs764942406 CA4254832 |
10 | G>V | No |
ClinGen ExAC gnomAD |
|
|
rs202090804 CA4254833 |
10 | G>W | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA367478077 rs1413572646 |
11 | A>P | No |
ClinGen gnomAD |
|
|
rs761731324 CA4254831 |
11 | A>V | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 12 | C>missing | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA367478049 rs1473213789 |
12 | C>S | No |
ClinGen gnomAD |
|
|
CA367478005 rs1395968010 |
13 | L>R | No |
ClinGen gnomAD |
|
|
rs973250941 CA158098468 |
14 | N>K | No |
ClinGen TOPMed |
|
|
rs746474307 CA367477958 |
15 | H>P | No |
ClinGen ExAC gnomAD |
|
|
CA4254827 rs746474307 |
15 | H>R | No |
ClinGen ExAC gnomAD |
|
|
rs145887588 CA4254828 |
15 | H>Y | No |
ClinGen ESP ExAC TOPMed |
|
|
rs1353488841 CA367477922 |
16 | F>L | No |
ClinGen TOPMed |
|
|
CA367476894 rs1163411332 |
20 | S>C | No |
ClinGen TOPMed gnomAD |
|
|
CA4254802 rs755310110 |
20 | S>N | No |
ClinGen ExAC gnomAD |
|
|
rs1583726906 CA367476881 |
20 | S>R | No |
ClinGen Ensembl |
|
|
rs1189431144 CA367476840 |
23 | I>T | No |
ClinGen gnomAD |
|
|
rs1364238179 CA367476832 |
24 | A>T | No |
ClinGen TOPMed |
|
|
rs1421260438 CA367476814 |
25 | K>R | No |
ClinGen TOPMed |
|
|
CA367476795 rs780317696 |
27 | A>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA367476794 rs780317696 |
27 | A>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs780317696 CA4254800 |
27 | A>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA4254799 rs758455511 |
29 | T>I | No |
ClinGen ExAC gnomAD |
|
|
rs778688123 CA4254797 |
30 | C>G | No |
ClinGen ExAC gnomAD |
|
|
CA367476749 rs1304081753 |
30 | C>Y | No |
ClinGen TOPMed |
|
|
CA367476726 rs1243581487 |
31 | T>S | No |
ClinGen gnomAD |
|
|
CA4254794 rs763893952 |
32 | L>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA4254792 rs752394885 |
33 | R>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs554018144 CA367476699 |
33 | R>H | No |
ClinGen gnomAD |
|
|
CA158097965 rs554018144 |
33 | R>P | No |
ClinGen gnomAD |
|
|
rs1015917843 CA367476642 |
35 | S>I | No |
ClinGen TOPMed gnomAD |
|
|
rs1015917843 CA158097956 |
35 | S>N | No |
ClinGen TOPMed gnomAD |
|
|
CA4254790 rs759095619 |
35 | S>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs773958274 CA4254789 |
36 | P>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA367476601 rs1423186911 |
37 | D>G | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
CA4254787 rs28910274 |
43 | L>F | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs200244554 CA4254786 |
44 | C>Y | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1201163815 CA367476399 |
45 | D>A | No |
ClinGen gnomAD |
|
|
rs572690669 CA4254785 |
46 | K>R | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs1312515924 CA367476341 |
48 | A>T | No |
ClinGen gnomAD |
|
|
rs1251131745 CA367476315 |
49 | N>D | No |
ClinGen TOPMed |
|
|
CA4254782 rs780223767 |
49 | N>S | No |
ClinGen ExAC gnomAD |
|
|
rs780223767 CA4254783 |
49 | N>T | No |
ClinGen ExAC gnomAD |
|
|
rs11551144 CA158097894 |
54 | M>V | No |
ClinGen Ensembl |
|
|
CA367476149 rs1441417649 |
56 | C>W | No |
ClinGen TOPMed |
|
|
CA367476065 rs1275099670 |
60 | Q>H | No |
ClinGen TOPMed gnomAD |
|
|
rs1176574912 CA367476067 |
60 | Q>L | No |
ClinGen TOPMed |
|
|
rs771041168 CA4254756 |
61 | E>K | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs749387979 CA367475981 |
62 | N>D | No |
ClinGen ExAC gnomAD |
|
|
CA4254755 rs749387979 |
62 | N>Y | No |
ClinGen ExAC gnomAD |
|
|
rs1467698553 CA367475952 |
63 | F>L | No |
ClinGen TOPMed |
|
|
CA4254752 rs1554293188 |
65 | N>H | No |
ClinGen Ensembl |
|
|
rs1408682972 CA367475921 |
66 | E>* | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed gnomAD |
|
rs1408682972 CA367475923 |
66 | E>K | No |
ClinGen TOPMed gnomAD |
|
|
CA4254750 rs142407794 |
68 | Q>H | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs781076158 CA4254748 |
69 | M>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs748118434 CA4254749 |
69 | M>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA4254747 rs754824991 |
71 | G>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA4254746 rs751218600 |
71 | G>V | No |
ClinGen ExAC gnomAD |
|
|
rs1210122585 CA367475876 |
72 | V>A | No |
ClinGen gnomAD |
|
|
CA367475881 rs1240868920 |
72 | V>I | No |
ClinGen TOPMed gnomAD |
|
|
CA4254744 rs757900445 |
73 | S>A | No |
ClinGen ExAC gnomAD |
|
|
rs749937055 CA4254743 |
74 | A>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs570029976 CA4254741 CA367475844 |
77 | N>K | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA4254742 rs371092744 |
77 | N>S | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA158097731 rs995696177 |
78 | E>A | No |
ClinGen Ensembl |
|
|
rs879014099 CA158097727 |
80 | Y>C | No |
ClinGen gnomAD |
|
|
CA367475813 rs1334936728 |
82 | E>* | No |
ClinGen gnomAD |
|
|
CA4254738 rs202060328 |
85 | S>L | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs202060328 CA4254739 |
85 | S>W | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs201091914 CA4254736 |
86 | E>K | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA158097705 rs890857470 |
89 | S>F | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed gnomAD |
|
CA367475767 rs890857470 |
89 | S>Y | No |
ClinGen TOPMed gnomAD |
|
|
CA4254735 rs567292691 |
90 | R>* | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen 1000Genomes ExAC NCI-TCGA TOPMed gnomAD |
|
CA4254734 rs773375727 |
90 | R>P | No |
ClinGen ExAC gnomAD |
|
|
rs548696788 CA367475735 |
95 | A>P | No |
ClinGen TOPMed |
|
|
rs548696788 CA158097697 |
95 | A>S | No |
ClinGen TOPMed |
|
|
rs149049902 CA4254732 |
101 | L>S | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA367475686 rs1342494080 |
102 | K>R | No |
ClinGen TOPMed |
|
|
CA158097679 rs1051302184 |
103 | I>V | No |
ClinGen Ensembl |
|
|
CA367475672 rs1383042472 |
104 | K>R | No |
ClinGen TOPMed gnomAD |
|
|
CA367475658 rs932448154 |
106 | T>I | No |
ClinGen gnomAD |
|
|
CA158097664 rs932448154 |
106 | T>S | No |
ClinGen gnomAD |
|
|
CA367475657 rs1462366176 |
107 | N>H | No |
ClinGen gnomAD |
|
|
CA367475653 rs1485961031 |
107 | N>S | No |
ClinGen gnomAD |
|
|
rs901750458 CA158097657 |
109 | H>P | No |
ClinGen TOPMed gnomAD |
|
|
CA367475639 rs1277589872 |
109 | H>Y | No |
ClinGen TOPMed |
|
|
rs899482012 CA158097653 |
110 | F>L | No |
ClinGen Ensembl |
|
|
CA367475626 rs1445836673 |
111 | P>A | No |
ClinGen TOPMed gnomAD |
|
|
rs200875322 CA4254730 |
111 | P>H | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA367475625 rs1445836673 |
111 | P>S | No |
ClinGen TOPMed gnomAD |
|
|
CA367475627 rs1445836673 |
111 | P>T | No |
ClinGen TOPMed gnomAD |
|
|
rs1359145415 CA367475617 |
112 | C>F | No |
ClinGen gnomAD |
|
|
CA4254728 rs746826153 |
113 | L>F | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs779721301 CA4254727 |
114 | T>M | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
CA4254725 rs750116033 |
116 | S>A | No |
ClinGen ExAC gnomAD |
|
|
rs768071524 CA4254721 |
117 | V>E | No |
ClinGen ExAC gnomAD |
|
|
CA4254722 rs753201633 |
117 | V>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA367475593 rs753201633 |
117 | V>M | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
rs774619687 CA4254719 |
118 | E>D | No |
ClinGen ExAC gnomAD |
|
|
rs759924524 CA4254720 |
118 | E>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1325875533 CA367474824 |
120 | L>S | No |
ClinGen gnomAD |
|
|
rs761951127 CA4254693 |
121 | S>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs761951127 CA367474820 |
121 | S>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1309010889 CA367474794 |
122 | M>I | No |
ClinGen TOPMed |
|
|
CA158096348 rs769565341 |
122 | M>T | No |
ClinGen Ensembl |
|
|
CA367474811 rs1296106302 |
122 | M>V | No |
ClinGen TOPMed |
|
|
CA367474770 rs1272603961 |
124 | S>N | No |
ClinGen TOPMed gnomAD |
|
|
CA4254691 rs768800136 |
125 | S>R | No |
ClinGen ExAC gnomAD |
|
|
rs2307261 CA4254690 VAR_033999 |
126 | S>G | No |
ClinGen UniProt ESP ExAC TOPMed dbSNP gnomAD |
|
|
CA4254689 rs368138281 |
127 | R>C | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs990421342 CA158096333 |
127 | R>H | No |
ClinGen TOPMed gnomAD |
|
|
rs990421342 CA367474722 |
127 | R>L | No |
ClinGen TOPMed gnomAD |
|
| TCGA novel | 128 | I>F | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs745724153 CA4254688 |
128 | I>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs745724153 CA4254687 |
128 | I>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs963026262 CA158096318 |
128 | I>V | No |
ClinGen Ensembl |
|
|
CA4254686 rs778515951 |
130 | T>S | No |
ClinGen ExAC gnomAD |
|
|
CA158096311 rs983371620 |
131 | H>R | No |
ClinGen Ensembl |
|
|
CA4254685 rs770612941 |
132 | D>N | No |
ClinGen ExAC gnomAD |
|
|
CA4254684 rs374782041 |
133 | I>N | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA367474650 rs1406282119 |
133 | I>V | No |
ClinGen gnomAD |
|
|
rs370417384 CA4254683 |
134 | P>L | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ESP ExAC NCI-TCGA TOPMed gnomAD |
|
rs370417384 CA367474628 |
134 | P>R | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1161884207 CA367474604 |
136 | K>R | No |
ClinGen TOPMed gnomAD |
|
| TCGA novel | 144 | K>N | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs780666620 CA4254680 |
144 | K>T | No |
ClinGen ExAC |
|
|
rs758666500 CA4254679 |
145 | D>G | No |
ClinGen ExAC gnomAD |
|
|
rs2307254 CA367474441 |
147 | Q>* | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs2307254 CA367474444 |
147 | Q>E | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
VAR_025414 rs2307254 CA4254678 |
147 | Q>K | No |
ClinGen UniProt 1000Genomes ESP ExAC TOPMed dbSNP gnomAD |
|
|
CA367474436 rs1203161065 |
147 | Q>L | No |
ClinGen gnomAD |
|
|
CA4254677 rs765725449 |
149 | P>L | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
| TCGA novel | 150 | V>L | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA367474351 rs1316203636 |
154 | P>A | No |
ClinGen TOPMed gnomAD |
|
|
CA367474350 rs1316203636 |
154 | P>T | No |
ClinGen TOPMed gnomAD |
|
|
CA367474343 rs1247881572 |
155 | D>N | No |
ClinGen gnomAD |
|
|
CA4254652 rs752863886 |
157 | S>I | No |
ClinGen ExAC gnomAD |
|
|
rs756128834 CA4254653 |
157 | S>R | No |
ClinGen ExAC gnomAD |
|
|
CA367474221 rs1428560343 |
158 | I>M | No |
ClinGen gnomAD |
|
|
rs767526776 CA4254651 |
158 | I>N | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA158095483 rs767526776 |
158 | I>T | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 158 | I>V | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA158095482 rs993645749 |
160 | L>* | No |
ClinGen Ensembl |
|
|
rs759420995 CA4254650 |
160 | L>F | No |
ClinGen ExAC gnomAD |
|
|
rs774286190 CA4254649 |
161 | P>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1562590048 CA367474073 |
165 | T>A | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen Ensembl NCI-TCGA |
|
CA4254647 rs762795092 |
166 | M>T | No |
ClinGen ExAC gnomAD |
|
|
CA4254648 rs139623972 |
166 | M>V | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs772715878 CA4254646 |
167 | K>E | No |
ClinGen ExAC gnomAD |
|
|
CA158095447 rs963706140 |
167 | K>N | No |
ClinGen TOPMed gnomAD |
|
|
rs769525580 CA4254645 |
168 | S>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA367473954 rs1460468394 |
170 | V>M | No |
ClinGen gnomAD |
|
|
CA367473844 rs1260649152 |
173 | M>I | Variant assessed as Somatic; 4.631e-05 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
| TCGA novel | 173 | M>N | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA158095426 rs1018212456 |
173 | M>T | No |
ClinGen TOPMed |
|
|
rs901600537 CA158095418 |
175 | N>T | No |
ClinGen TOPMed gnomAD |
|
|
CA158095384 rs375639721 |
176 | I>T | No |
ClinGen TOPMed |
|
|
rs776155080 CA4254643 |
176 | I>V | No |
ClinGen ExAC gnomAD |
|
|
rs758303126 CA4254610 |
181 | V>I | No |
ClinGen ExAC gnomAD |
|
|
rs1476660827 CA367474284 |
182 | I>V | No |
ClinGen gnomAD |
|
|
rs1374205743 CA367474243 |
184 | A>G | No |
ClinGen gnomAD |
|
|
CA158124480 rs1046961710 |
185 | N>K | No |
ClinGen TOPMed |
|
|
CA4254608 rs765013904 |
188 | G>R | No |
ClinGen ExAC gnomAD |
|
|
CA4254606 rs763890469 |
192 | L>F | No |
ClinGen ExAC gnomAD |
|
|
rs138848570 CA367474067 |
196 | T>I | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs138848570 CA4254604 |
196 | T>S | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs771730666 CA4254602 |
199 | V>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs761654334 CA158124374 |
200 | C>R | No |
ClinGen gnomAD |
|
|
CA4254601 rs763461631 |
200 | C>S | No |
ClinGen ExAC gnomAD |
|
|
rs773598798 CA4254600 |
203 | T>N | No |
ClinGen ExAC gnomAD |
|
|
rs1237795972 CA367473913 |
207 | D>N | No |
ClinGen gnomAD |
|
|
CA367473877 rs575534013 |
209 | G>A | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA4254599 rs575534013 |
209 | G>E | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs1462690540 CA367473862 |
210 | N>K | No |
ClinGen gnomAD |
|
|
rs1042435792 CA158124359 |
210 | N>S | No |
ClinGen gnomAD |
|
|
rs1263777627 CA367473852 |
211 | P>L | No |
ClinGen gnomAD |
|
|
rs748508349 CA4254598 |
212 | P>L | No |
ClinGen ExAC gnomAD |
|
|
CA4254597 rs781361344 |
213 | L>* | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1306763036 CA367473493 |
215 | S>F | No |
ClinGen gnomAD |
|
|
rs1198579054 CA367473464 |
219 | H>L | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed gnomAD |
|
CA367473466 rs1198579054 |
219 | H>R | No |
ClinGen TOPMed gnomAD |
|
|
VAR_025415 CA4254580 rs3176588 |
221 | D>E | No |
ClinGen UniProt 1000Genomes ESP ExAC TOPMed dbSNP gnomAD |
|
|
rs752411443 CA4254581 |
221 | D>Y | No |
ClinGen ExAC gnomAD |
|
|
rs759036115 CA4254579 |
223 | N>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs765701835 CA4254577 |
224 | V>M | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1217424557 CA367473427 |
225 | E>Q | No |
ClinGen gnomAD |
|
|
CA158122860 rs776350827 |
226 | H>R | No |
ClinGen gnomAD |
|
|
rs762413622 CA4254576 |
227 | M>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1420788573 CA367473400 |
228 | A>V | No |
ClinGen gnomAD |
|
|
rs200031230 CA4254575 |
229 | E>D | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
CA367473369 rs1386091463 |
232 | I>K | No |
ClinGen gnomAD |
|
|
CA4254574 rs769018345 |
232 | I>L | No |
ClinGen ExAC gnomAD |
|
|
CA4254573 rs548463200 |
232 | I>M | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA4254572 rs775753755 |
233 | D>G | No |
ClinGen ExAC gnomAD |
|
|
CA4254571 rs772175797 |
234 | I>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA158122835 rs565803246 |
234 | I>V | No |
ClinGen Ensembl |
|
|
rs369947303 CA4254570 |
236 | K>R | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1487885002 CA367473325 |
237 | L>F | No |
ClinGen TOPMed gnomAD |
|
|
CA4254569 CA367473310 rs528436783 |
239 | Q>H | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs1283642678 CA367473313 |
239 | Q>P | No |
ClinGen TOPMed gnomAD |
|
|
rs1283642678 CA367473312 |
239 | Q>R | No |
ClinGen TOPMed gnomAD |
|
|
CA4254568 rs757107208 |
240 | F>L | No |
ClinGen ExAC gnomAD |
|
|
rs1264458856 CA367473303 |
240 | F>L | No |
ClinGen gnomAD |
|
|
CA4254567 rs749261354 |
242 | A>D | No |
ClinGen ExAC gnomAD |
|
|
CA367473291 rs1295626546 |
243 | G>R | No |
ClinGen gnomAD |
|
|
CA367473283 rs1340390102 |
244 | Q>* | No |
ClinGen gnomAD |
|
|
rs1229068224 CA367473265 |
246 | V>A | No |
ClinGen TOPMed |
|
|
CA4254563 rs752394896 |
249 | T>I | No |
ClinGen ExAC gnomAD |
|
|
rs372086665 CA158122759 |
250 | K>E | No |
ClinGen ESP |
|
|
rs369406174 CA4254561 |
252 | L>* | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA4254562 rs79656108 |
252 | L>I | No |
ClinGen ExAC gnomAD |
|
|
rs199759985 CA4254560 |
253 | C>R | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA158120395 rs769754613 |
254 | N>S | No |
ClinGen Ensembl |
|
|
rs751237091 CA4254539 |
255 | I>T | No |
ClinGen ExAC gnomAD |
|
|
CA367472983 rs1439251228 |
256 | V>A | No |
ClinGen gnomAD |
|
|
CA367472987 rs1196408323 |
256 | V>L | No |
ClinGen gnomAD |
|
|
CA4254538 rs779360913 |
260 | M>V | No |
ClinGen ExAC gnomAD |
|
|
CA367472927 rs1197514781 |
261 | V>L | No |
ClinGen TOPMed gnomAD |
|
|
rs1197514781 CA367472930 |
261 | V>M | No |
ClinGen TOPMed gnomAD |
|
|
CA4254537 rs200372941 |
266 | L>F | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs1264418418 CA367472871 |
266 | L>P | No |
ClinGen gnomAD |
|
|
rs1346260670 CA367472861 |
267 | H>L | No |
ClinGen gnomAD |
|
|
rs754327169 CA4254536 |
267 | H>N | No |
ClinGen ExAC gnomAD |
|
|
CA4254534 rs553523764 |
269 | D>E | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA4254535 rs10253916 |
269 | D>N | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA4254532 rs767949931 |
270 | V>L | No |
ClinGen ExAC gnomAD |
|
|
CA367472833 rs767949931 |
270 | V>M | No |
ClinGen ExAC gnomAD |
|
|
CA4254530 rs774639525 |
272 | L>F | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs774639525 CA4254531 |
272 | L>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1446254392 CA367472809 |
273 | Q>* | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
rs771131844 CA4254529 |
274 | Y>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA367472751 rs1379315871 |
278 | A>P | No |
ClinGen TOPMed |
|
|
rs763185314 CA4254527 |
278 | A>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA367472738 rs1373060579 |
279 | L>Q | No |
ClinGen TOPMed |
No associated diseases with O60921
No regional properties for O60921
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| No domain, repeats, and functional sites for O60921 | |||
Functions
6 GO annotations of cellular component
| Name | Definition |
|---|---|
| checkpoint clamp complex | Conserved heterotrimeric complex of PCNA-like proteins that is loaded onto DNA at sites of DNA damage. |
| cytosol | The part of the cytoplasm that does not contain organelles but which does contain other particulate matter, such as protein complexes. |
| nucleolus | A small, dense body one or more of which are present in the nucleus of eukaryotic cells. It is rich in RNA and protein, is not bounded by a limiting membrane, and is not seen during mitosis. Its prime function is the transcription of the nucleolar DNA into 45S ribosomal-precursor RNA, the processing of this RNA into 5.8S, 18S, and 28S components of ribosomal RNA, and the association of these components with 5S RNA and proteins synthesized outside the nucleolus. This association results in the formation of ribonucleoprotein precursors; these pass into the cytoplasm and mature into the 40S and 60S subunits of the ribosome. |
| nucleoplasm | That part of the nuclear content other than the chromosomes or the nucleolus. |
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
| site of double-strand break | A region of a chromosome at which a DNA double-strand break has occurred. DNA damage signaling and repair proteins accumulate at the lesion to respond to the damage and repair the DNA to form a continuous DNA helix. |
No GO annotations of molecular function
| Name | Definition |
|---|---|
| No GO annotations for molecular function |
14 GO annotations of biological process
| Name | Definition |
|---|---|
| cellular response to DNA damage stimulus | Any process that results in a change in state or activity of a cell (in terms of movement, secretion, enzyme production, gene expression, etc.) as a result of a stimulus indicating damage to its DNA from environmental insults or errors during metabolism. |
| cellular response to ionizing radiation | Any process that results in a change in state or activity of a cell (in terms of movement, secretion, enzyme production, gene expression, etc.) as a result of a ionizing radiation stimulus. Ionizing radiation is radiation with sufficient energy to remove electrons from atoms and may arise from spontaneous decay of unstable isotopes, resulting in alpha and beta particles and gamma rays. Ionizing radiation also includes X-rays. |
| DNA damage checkpoint signaling | A signal transduction process that contributes to a DNA damage checkpoint. |
| DNA repair | The process of restoring DNA after damage. Genomes are subject to damage by chemical and physical agents in the environment (e.g. UV and ionizing radiations, chemical mutagens, fungal and bacterial toxins, etc.) and by free radicals or alkylating agents endogenously generated in metabolism. DNA is also damaged because of errors during its replication. A variety of different DNA repair pathways have been reported that include direct reversal, base excision repair, nucleotide excision repair, photoreactivation, bypass, double-strand break repair pathway, and mismatch repair pathway. |
| double-strand break repair via homologous recombination | The error-free repair of a double-strand break in DNA in which the broken DNA molecule is repaired using homologous sequences. A strand in the broken DNA searches for a homologous region in an intact chromosome to serve as the template for DNA synthesis. The restoration of two intact DNA molecules results in the exchange, reciprocal or nonreciprocal, of genetic material between the intact DNA molecule and the broken DNA molecule. |
| embryo development ending in birth or egg hatching | The process whose specific outcome is the progression of an embryo over time, from zygote formation until the end of the embryonic life stage. The end of the embryonic life stage is organism-specific and may be somewhat arbitrary; for mammals it is usually considered to be birth, for insects the hatching of the first instar larva from the eggshell. |
| meiotic DNA integrity checkpoint signaling | A signal transduction process that controls cell cycle progression in response to changes in DNA structure by monitoring the integrity of the DNA during meiosis. The DNA integrity checkpoint begins with detection of DNA damage, defects in DNA structure or DNA replication, and ends with signal transduction. |
| mitotic DNA replication checkpoint signaling | A signal transduction process that contributes to a mitotic DNA replication checkpoint. |
| mitotic intra-S DNA damage checkpoint signaling | A mitotic cell cycle checkpoint that slows DNA synthesis in response to DNA damage by the prevention of new origin firing and the stabilization of slow replication fork progression. |
| nucleotide-excision repair | A DNA repair process in which a small region of the strand surrounding the damage is removed from the DNA helix as an oligonucleotide. The small gap left in the DNA helix is filled in by the sequential action of DNA polymerase and DNA ligase. Nucleotide excision repair recognizes a wide range of substrates, including damage caused by UV irradiation (pyrimidine dimers and 6-4 photoproducts) and chemicals (intrastrand cross-links and bulky adducts). |
| protein phosphorylation | The process of introducing a phosphate group on to a protein. |
| regulation of protein phosphorylation | Any process that modulates the frequency, rate or extent of addition of phosphate groups into an amino acid in a protein. |
| response to UV | Any process that results in a change in state or activity of a cell or an organism (in terms of movement, secretion, enzyme production, gene expression, etc.) as a result of an ultraviolet radiation (UV light) stimulus. Ultraviolet radiation is electromagnetic radiation with a wavelength in the range of 10 to 380 nanometers. |
| telomere maintenance | Any process that contributes to the maintenance of proper telomeric length and structure by affecting and monitoring the activity of telomeric proteins, the length of telomeric DNA and the replication and repair of the DNA. These processes includes those that shorten, lengthen, replicate and repair the telomeric DNA sequences. |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MKFRAKIVDG | ACLNHFTRIS | NMIAKLAKTC | TLRISPDKLN | FILCDKLANG | GVSMWCELEQ |
| 70 | 80 | 90 | 100 | 110 | 120 |
| ENFFNEFQME | GVSAENNEIY | LELTSENLSR | ALKTAQNARA | LKIKLTNKHF | PCLTVSVELL |
| 130 | 140 | 150 | 160 | 170 | 180 |
| SMSSSSRIVT | HDIPIKVIPR | KLWKDLQEPV | VPDPDVSIYL | PVLKTMKSVV | EKMKNISNHL |
| 190 | 200 | 210 | 220 | 230 | 240 |
| VIEANLDGEL | NLKIETELVC | VTTHFKDLGN | PPLASESTHE | DRNVEHMAEV | HIDIRKLLQF |
| 250 | 260 | 270 | |||
| LAGQQVNPTK | ALCNIVNNKM | VHFDLLHEDV | SLQYFIPALS |