F4JRF4
Gene name |
MYH (At4g12740, T20K18.90) |
Protein name |
Adenine DNA glycosylase |
Names |
MutY homolog, AtMYH |
Species |
Arabidopsis thaliana (Mouse-ear cress) |
KEGG Pathway |
ath:AT4G12740 |
EC number |
3.2.2.31: Hydrolyzing N-glycosyl compounds |
Protein Class |
|
Descriptions
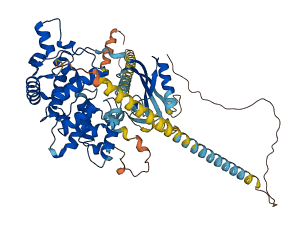
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
1 structures for F4JRF4
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| AF-F4JRF4-F1 | Predicted | AlphaFoldDB |
102 variants for F4JRF4
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
| ENSVATH06635479 | 2 | A>T | No | 1000Genomes | |
| ENSVATH11589489 | 3 | C>F | No | 1000Genomes | |
| tmp_4_7497530_G_C | 23 | Q>E | No | 1000Genomes | |
| ENSVATH06635478 | 23 | Q>P | No | 1000Genomes | |
| ENSVATH11589488 | 27 | T>I | No | 1000Genomes | |
| ENSVATH02805834 | 35 | V>A | No | 1000Genomes | |
| ENSVATH06635477 | 45 | Q>K | No | 1000Genomes | |
| ENSVATH11589487 | 54 | M>V | No | 1000Genomes | |
| tmp_4_7497421_T_C | 59 | E>G | No | 1000Genomes | |
| tmp_4_7497411_T_A | 62 | E>D | No | 1000Genomes | |
| ENSVATH02805832 | 69 | R>Q | No | 1000Genomes | |
| ENSVATH11589486 | 71 | A>E | No | 1000Genomes | |
| ENSVATH08333011 | 77 | E>G | No | 1000Genomes | |
| ENSVATH08333012 | 77 | E>Q | No | 1000Genomes | |
| tmp_4_7497364_T_G | 78 | E>A | No | 1000Genomes | |
| tmp_4_7497360_T_G | 79 | E>D | No | 1000Genomes | |
| ENSVATH02805831 | 80 | K>E | No | 1000Genomes | |
| ENSVATH11589452 | 80 | K>T | No | 1000Genomes | |
| ENSVATH11589451 | 81 | A>E | No | 1000Genomes | |
| ENSVATH11589450 | 82 | E>A | No | 1000Genomes | |
| ENSVATH06635475 | 85 | E>D | No | 1000Genomes | |
| ENSVATH06635474 | 86 | A>E | No | 1000Genomes | |
| tmp_4_7497330_G_T | 89 | D>E | No | 1000Genomes | |
| ENSVATH11589448 | 93 | A>S | No | 1000Genomes | |
| ENSVATH11589446 | 96 | E>K | No | 1000Genomes | |
| ENSVATH08333009 | 107 | E>A | No | 1000Genomes | |
| tmp_4_7497274_GCTT_GCTTCTT,TCTT,G | 108 | A>E | No | 1000Genomes | |
| ENSVATH14978755 | 108 | A>S | No | 1000Genomes | |
| ENSVATH06635471 | 110 | A>E | No | 1000Genomes | |
| ENSVATH14158378 | 112 | E>K | No | 1000Genomes | |
| tmp_4_7497259_T_G | 113 | E>A | No | 1000Genomes | |
| ENSVATH14158377 | 113 | E>K | No | 1000Genomes | |
| tmp_4_7497250_C_A | 116 | G>V | No | 1000Genomes | |
| ENSVATH06635470 | 119 | I>L | No | 1000Genomes | |
| ENSVATH06635469 | 130 | K>E | No | 1000Genomes | |
| tmp_4_7497202_C_A | 132 | R>I | No | 1000Genomes | |
| tmp_4_7497186_A_C | 137 | D>E | No | 1000Genomes | |
| ENSVATH14158376 | 184 | K>Q | No | 1000Genomes | |
| ENSVATH00496328 | 188 | Q>E | No | 1000Genomes | |
| ENSVATH06635467 | 197 | G>A | No | 1000Genomes | |
| ENSVATH00496323 | 204 | L>P | No | 1000Genomes | |
| tmp_4_7496631_C_T | 206 | V>I | No | 1000Genomes | |
| tmp_4_7496627_C_T | 207 | S>N | No | 1000Genomes | |
| ENSVATH11589387 | 217 | G>E | No | 1000Genomes | |
| ENSVATH06635443 | 220 | K>R | No | 1000Genomes | |
| ENSVATH11589361 | 280 | N>S | No | 1000Genomes | |
| tmp_4_7495715_G_T | 306 | D>E | No | 1000Genomes | |
| tmp_4_7495486_G_A | 354 | S>F | No | 1000Genomes | |
| tmp_4_7495474_C_T | 358 | R>H | No | 1000Genomes | |
| tmp_4_7495454_C_G | 365 | E>Q | No | 1000Genomes | |
| ENSVATH11589357 | 368 | T>M | No | 1000Genomes | |
| ENSVATH11589356 | 381 | A>T | No | 1000Genomes | |
| ENSVATH00496313 | 397 | N>S | No | 1000Genomes | |
| ENSVATH11589314 | 398 | L>P | No | 1000Genomes | |
| ENSVATH02805812 | 406 | R>K | No | 1000Genomes | |
| tmp_4_7495289_C_A | 420 | G>C | No | 1000Genomes | |
| tmp_4_7495246_T_C | 434 | D>G | No | 1000Genomes | |
| ENSVATH14158319 | 437 | T>A | No | 1000Genomes | |
| tmp_4_7495217_C_G | 444 | V>L | No | 1000Genomes | |
| ENSVATH00496310 | 451 | R>H | No | 1000Genomes | |
| ENSVATH00496309 | 459 | A>T | No | 1000Genomes | |
| ENSVATH00496308 | 492 | T>A | No | 1000Genomes | |
| ENSVATH00496306 | 493 | G>V | No | 1000Genomes | |
| ENSVATH00496305 | 496 | E>K | No | 1000Genomes | |
| ENSVATH06635430 | 501 | G>A | No | 1000Genomes | |
| ENSVATH06635430 | 501 | G>D | No | 1000Genomes | |
| tmp_4_7494963_G_T | 503 | A>E | No | 1000Genomes | |
| ENSVATH14158316 | 520 | L>M | No | 1000Genomes | |
| ENSVATH00496302 | 530 | P>R | No | 1000Genomes | |
| tmp_4_7494879_G_C | 531 | P>R | No | 1000Genomes | |
| tmp_4_7494877_A_G | 532 | F>L | No | 1000Genomes | |
| tmp_4_7494876_A_G | 532 | F>S | No | 1000Genomes | |
| tmp_4_7494868_G_C | 535 | Q>E | No | 1000Genomes | |
| tmp_4_7494867_T_C | 535 | Q>R | No | 1000Genomes | |
| tmp_4_7494864_T_C | 536 | H>R | No | 1000Genomes | |
| ENSVATH00496301 | 541 | S>P | No | 1000Genomes | |
| tmp_4_7494842_A_T | 543 | D>E | No | 1000Genomes | |
| ENSVATH11589309 | 544 | V>A | No | 1000Genomes | |
| ENSVATH00496300 | 545 | M>I | No | 1000Genomes | |
| tmp_4_7494835_C_T | 546 | V>I | No | 1000Genomes | |
| ENSVATH00496299 | 547 | E>D | No | 1000Genomes | |
| ENSVATH06635429 | 558 | Q>R | No | 1000Genomes | |
| ENSVATH02805809 | 564 | S>R | No | 1000Genomes | |
| tmp_4_7494775_C_G | 566 | A>P | No | 1000Genomes | |
| ENSVATH00496298 | 569 | F>L | No | 1000Genomes | |
| tmp_4_7494748_T_C | 575 | I>V | No | 1000Genomes | |
| tmp_4_7494733_G_A | 580 | R>* | No | 1000Genomes | |
| ENSVATH00496297 | 580 | R>Q | No | 1000Genomes | |
| ENSVATH14158294 | 584 | N>D | No | 1000Genomes | |
| ENSVATH00496296 | 584 | N>K | No | 1000Genomes | |
| tmp_4_7494699_G_T | 591 | T>K | No | 1000Genomes | |
| ENSVATH02805807 | 592 | L>F | No | 1000Genomes | |
| ENSVATH06635428 | 594 | F>Y | No | 1000Genomes | |
| ENSVATH00496295 | 599 | F>L | No | 1000Genomes | |
| tmp_4_7494669_C_A | 601 | S>I | No | 1000Genomes | |
| ENSVATH06635427 | 601 | S>R | No | 1000Genomes | |
| tmp_4_7494666_G_T | 602 | S>Y | No | 1000Genomes | |
| ENSVATH06635426 | 606 | L>F | No | 1000Genomes | |
| ENSVATH00496294 | 617 | L>M | No | 1000Genomes | |
| tmp_4_7494616_T_A | 619 | S>C | No | 1000Genomes | |
| tmp_4_7494589_C_A | 628 | G>C | No | 1000Genomes | |
| ENSVATH02805806 | 628 | G>D | No | 1000Genomes |
No associated diseases with F4JRF4
Functions
| Description | ||
|---|---|---|
| EC Number | 3.2.2.31 | Hydrolyzing N-glycosyl compounds |
| Subcellular Localization |
|
|
| PANTHER Family | ||
| PANTHER Subfamily | ||
| PANTHER Protein Class | ||
| PANTHER Pathway Category | No pathway information available | |
1 GO annotations of cellular component
| Name | Definition |
|---|---|
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
6 GO annotations of molecular function
| Name | Definition |
|---|---|
| 4 iron, 4 sulfur cluster binding | Binding to a 4 iron, 4 sulfur (4Fe-4S) cluster; this cluster consists of four iron atoms, with the inorganic sulfur atoms found between the irons and acting as bridging ligands. |
| 8-oxo-7,8-dihydroguanine DNA N-glycosylase activity | Catalysis of the removal of 8-oxo-7,8-dihydroguanine bases by cleaving the N-C1' glycosidic bond between the oxidized purine and the deoxyribose sugar. |
| adenine/guanine mispair binding | Binding to a double-stranded DNA region containing an A/G mispair. |
| metal ion binding | Binding to a metal ion. |
| oxidized purine DNA binding | Binding to a DNA region containing an oxidized purine residue. |
| purine-specific mismatch base pair DNA N-glycosylase activity | Catalysis of the removal of purines present in mismatches, especially opposite oxidized purines, by cleaving the N-C1' glycosidic bond between the target damaged DNA base and the deoxyribose sugar. The reaction releases a free base and leaves an apurinic (AP) site. |
2 GO annotations of biological process
| Name | Definition |
|---|---|
| base-excision repair | In base excision repair, an altered base is removed by a DNA glycosylase enzyme, followed by excision of the resulting sugar phosphate. The small gap left in the DNA helix is filled in by the sequential action of DNA polymerase and DNA ligase. |
| mismatch repair | A system for the correction of errors in which an incorrect base, which cannot form hydrogen bonds with the corresponding base in the parent strand, is incorporated into the daughter strand. The mismatch repair system promotes genomic fidelity by repairing base-base mismatches, insertion-deletion loops and heterologies generated during DNA replication and recombination. |
1 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| Q9UIF7 | MUTYH | Adenine DNA glycosylase | Homo sapiens (Human) | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MACLLRVALN | PTFERSTVAS | QRQNPKTILS | FHCKVSSFKT | KTMSQSFAPR | EKLMRKCREK |
| 70 | 80 | 90 | 100 | 110 | 120 |
| KEAEREAERE | AEREAEEEEK | AEEAEAEADK | EEAEEESEEE | EEEEEEEAEA | EEEALGGDIE |
| 130 | 140 | 150 | 160 | 170 | 180 |
| DLFSENETQK | IRMGLLDWYD | VNKRDLPWRN | RRSESEKERR | AYEVWVSEIM | LQQTRVQTVM |
| 190 | 200 | 210 | 220 | 230 | 240 |
| KYYKRWMQKW | PTIYDLGQAS | LENLIVSRSR | ELSFLRGNEK | KEVNEMWAGL | GYYRRARFLL |
| 250 | 260 | 270 | 280 | 290 | 300 |
| EGAKMVVAGT | EGFPNQASSL | MKVKGIGQYT | AGAIASIAFN | EAVPVVDGNV | IRVLARLKAI |
| 310 | 320 | 330 | 340 | 350 | 360 |
| SANPKDRLTA | RNFWKLAAQL | VDPSRPGDFN | QSLMELGATL | CTVSKPSCSS | CPVSSQCRAF |
| 370 | 380 | 390 | 400 | 410 | 420 |
| SLSEENRTIS | VTDYPTKVIK | AKPRHDFCCV | CVLEIHNLER | NQSGGRFVLV | KRPEQGLLAG |
| 430 | 440 | 450 | 460 | 470 | 480 |
| LWEFPSVILN | EEADSATRRN | AINVYLKEAF | RFHVELKKAC | TIVSREELGE | FVHIFTHIRR |
| 490 | 500 | 510 | 520 | 530 | 540 |
| KVYVELLVVQ | LTGGTEDLFK | GQAKDTLTWK | CVSSDVLSTL | GLTSAVRKVP | PFRLQHIKRL |
| 550 | 560 | 570 | 580 | 590 | 600 |
| SLDVMVEKEQ | ILECRCIQWL | KHTSKAYLFL | MSHQIEQPYR | GNENSHDLLL | TLFFMLLSFY |
| 610 | 620 | ||||
| SSCLALGIKF | GDLGLKLNSL | VSTEKSDGDV |