F4I366
Gene name |
NRPA2 |
Protein name |
DNA-directed RNA polymerase I subunit 2 |
Names |
DNA-directed RNA polymerase I subunit RPA2, DNA polymerase I subunit A2, Nuclear RNA polymerase A2 |
Species |
Arabidopsis thaliana (Mouse-ear cress) |
KEGG Pathway |
ath:AT1G29940 |
EC number |
2.7.7.6: Nucleotidyltransferases |
Protein Class |
|
Descriptions
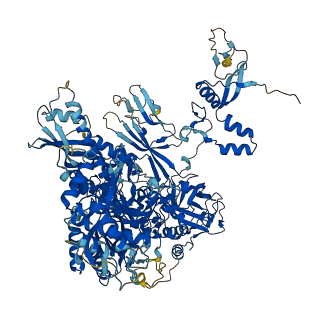
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
1 structures for F4I366
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| AF-F4I366-F1 | Predicted | AlphaFoldDB |
51 variants for F4I366
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
| ENSVATH04669500 | 4 | N>K | No | 1000Genomes | |
| ENSVATH01126039 | 12 | T>S | No | 1000Genomes | |
| ENSVATH12326674 | 38 | L>I | No | 1000Genomes | |
| tmp_1_10486541_G_C | 44 | R>G | No | 1000Genomes | |
| ENSVATH14001818 | 47 | P>T | No | 1000Genomes | |
| tmp_1_10486519_T_C | 51 | Y>C | No | 1000Genomes | |
| ENSVATH12326673 | 60 | S>T | No | 1000Genomes | |
| ENSVATH04669493 | 86 | L>F | No | 1000Genomes | |
| ENSVATH00050824 | 95 | I>V | No | 1000Genomes | |
| ENSVATH12326670 | 100 | T>M | No | 1000Genomes | |
| tmp_1_10486180_C_T | 102 | M>I | No | 1000Genomes | |
| ENSVATH04669479 | 136 | K>N | No | 1000Genomes | |
| tmp_1_10485794_T_C | 150 | T>A | No | 1000Genomes | |
| ENSVATH00050821 | 179 | S>G | No | 1000Genomes | |
| tmp_1_10485130_G_A | 207 | S>L | No | 1000Genomes | |
| ENSVATH04669460 | 248 | D>E | No | 1000Genomes | |
| tmp_1_10484742_G_C | 255 | L>V | No | 1000Genomes | |
| tmp_1_10484625_G_A | 294 | R>C | No | 1000Genomes | |
| ENSVATH12326594 | 296 | Q>H | No | 1000Genomes | |
| ENSVATH00050819 | 299 | K>N | No | 1000Genomes | |
| ENSVATH12326591 | 319 | I>S | No | 1000Genomes | |
| ENSVATH12326591 | 319 | I>T | No | 1000Genomes | |
| ENSVATH14001780 | 323 | A>V | No | 1000Genomes | |
| tmp_1_10484150_G_C | 337 | H>D | No | 1000Genomes | |
| tmp_1_10483997_A_G | 359 | L>S | No | 1000Genomes | |
| ENSVATH04669447 | 401 | L>M | No | 1000Genomes | |
| ENSVATH04669445 | 408 | F>Y | No | 1000Genomes | |
| tmp_1_10483424_T_G | 420 | I>L | No | 1000Genomes | |
| tmp_1_10483379_A_T | 435 | L>M | No | 1000Genomes | |
| tmp_1_10482448_G_A | 528 | S>F | No | 1000Genomes | |
| ENSVATH14001776 | 529 | K>Q | No | 1000Genomes | |
| ENSVATH04669426 | 532 | I>V | No | 1000Genomes | |
| ENSVATH14001775 | 614 | S>R | No | 1000Genomes | |
| tmp_1_10482100_A_G | 615 | M>T | No | 1000Genomes | |
| ENSVATH00050806 | 632 | I>V | No | 1000Genomes | |
| tmp_1_10482041_C_T | 635 | V>I | No | 1000Genomes | |
| tmp_1_10481774_C_T | 696 | D>N | No | 1000Genomes | |
| ENSVATH04669415 | 733 | Q>L | No | 1000Genomes | |
| tmp_1_10480894_A_T | 806 | F>Y | No | 1000Genomes | |
| ENSVATH04669402 | 819 | K>N | No | 1000Genomes | |
| ENSVATH04669401 | 820 | A>T | No | 1000Genomes | |
| tmp_1_10480653_T_C | 851 | T>A | No | 1000Genomes | |
| ENSVATH00050802 | 912 | L>S | No | 1000Genomes | |
| tmp_1_10480376_C_T | 918 | M>I | No | 1000Genomes | |
| tmp_1_10480363_C_G | 923 | V>L | No | 1000Genomes | |
| ENSVATH12325753 | 972 | K>E | No | 1000Genomes | |
| tmp_1_10479997_G_A | 991 | S>F | No | 1000Genomes | |
| tmp_1_10479995_T_A | 992 | M>L | No | 1000Genomes | |
| ENSVATH12325752 | 1003 | T>S | No | 1000Genomes | |
| tmp_1_10479524_T_C | 1112 | Q>R | No | 1000Genomes | |
| tmp_1_10479349_T_A | 1170 | L>F | No | 1000Genomes |
No associated diseases with F4I366
7 regional properties for F4I366
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| domain | DNA-directed RNA polymerase, subunit 2, hybrid-binding domain | 688 - 1058 | IPR007120 |
| conserved_site | RNA polymerase, beta subunit, conserved site | 896 - 908 | IPR007121 |
| domain | RNA polymerase Rpb2, domain 7 | 1060 - 1169 | IPR007641 |
| domain | RNA polymerase Rpb2, domain 2 | 192 - 371 | IPR007642 |
| domain | RNA polymerase, beta subunit, protrusion | 21 - 411 | IPR007644 |
| domain | RNA polymerase Rpb2, domain 3 | 459 - 522 | IPR007645 |
| domain | DNA-directed RNA polymerase I subunit RPA2, domain 4 | 576 - 633 | IPR009674 |
Functions
| Description | ||
|---|---|---|
| EC Number | 2.7.7.6 | Nucleotidyltransferases |
| Subcellular Localization |
|
|
| PANTHER Family | ||
| PANTHER Subfamily | ||
| PANTHER Protein Class | ||
| PANTHER Pathway Category | No pathway information available | |
1 GO annotations of cellular component
| Name | Definition |
|---|---|
| RNA polymerase I complex | RNA polymerase I, one of three nuclear DNA-directed RNA polymerases found in all eukaryotes, is a multisubunit complex; typically it produces rRNAs. Two large subunits comprise the most conserved portion including the catalytic site and share similarity with other eukaryotic and bacterial multisubunit RNA polymerases. The remainder of the complex is composed of smaller subunits (generally ten or more), some of which are also found in RNA polymerase III and others of which are also found in RNA polymerases II and III. Although the core is competent to mediate ribonucleic acid synthesis, it requires additional factors to select the appropriate template. |
4 GO annotations of molecular function
| Name | Definition |
|---|---|
| DNA binding | Any molecular function by which a gene product interacts selectively and non-covalently with DNA (deoxyribonucleic acid). |
| DNA-directed 5'-3' RNA polymerase activity | Catalysis of the reaction: nucleoside triphosphate + RNA(n) = diphosphate + RNA(n+1). Utilizes a DNA template, i.e. the catalysis of DNA-template-directed extension of the 3'-end of an RNA strand by one nucleotide at a time. Can initiate a chain 'de novo'. |
| metal ion binding | Binding to a metal ion. |
| ribonucleoside binding | Binding to a ribonucleoside, a compound consisting of a purine or pyrimidine nitrogenous base linked to ribose. |
3 GO annotations of biological process
| Name | Definition |
|---|---|
| DNA-templated transcription | The synthesis of an RNA transcript from a DNA template. |
| megagametogenesis | The process whose specific outcome is the progression of the embryo sac over time, from its formation as the megaspore to the mature structure. The process begins when three of the four haploid megaspores disintegrate, and the fourth undergoes mitosis giving rise to a binucleate syncytial embryo sac. The two haploid nuclei migrate to the opposite poles of the embryo sac and then undergo two rounds of mitosis generating four haploid nuclei at each pole. One nucleus from each set of four migrates to the center of the cell. Cellularization occurs, resulting in an eight-nucleate seven-celled structure. This structure contains two synergid cells and an egg cell at the micropylar end, and three antipodal cells at the other end. A binucleate endosperm mother cell is formed at the center. |
| ribosome biogenesis | A cellular process that results in the biosynthesis of constituent macromolecules, assembly, and arrangement of constituent parts of ribosome subunits; includes transport to the sites of protein synthesis. |
No homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| No homologous proteins | ||||
| 10 | 20 | 30 | 40 | 50 | 60 |
| MVVNAKDSTV | PTMEDFKELH | NLVTHHIESF | DYMTLKGLDV | MFNRIKPVSV | YDPNTENELS |
| 70 | 80 | 90 | 100 | 110 | 120 |
| IWLENPLVFA | PQKESFKSTS | RKEPLLPFEC | RQAKISYTGT | FMADVCFKYN | DGVVVRDKFD |
| 130 | 140 | 150 | 160 | 170 | 180 |
| FGQFPIMLMS | KLCSLKGADC | RKLLKCKEST | SEMGGYFILN | GIERVFRCVI | APKRNHPTSM |
| 190 | 200 | 210 | 220 | 230 | 240 |
| IRNSFRDRKE | GYSSKAVVTR | CVRDDQSSVT | VKLYYLRNGS | ARVGFWIVGR | EYLLPVGLVL |
| 250 | 260 | 270 | 280 | 290 | 300 |
| KALTNSCDEE | IYESLNCCYS | EHYGRGDGAI | GTQLVRERAK | IILDEVRDLG | LFTREQCRKH |
| 310 | 320 | 330 | 340 | 350 | 360 |
| LGQHFQPVLD | GVKKESLSIV | AEAVLRDYLF | VHLDNDHDKF | NLLIFIIQKL | YSLVDQTSLP |
| 370 | 380 | 390 | 400 | 410 | 420 |
| DNPDSLQNQE | ILVPGHVITI | YLKEKLEEWL | RKCKSLLKDE | LDNTNSKFSF | ESLADVKKLI |
| 430 | 440 | 450 | 460 | 470 | 480 |
| NKNPPRSIGT | SIETLLKTGA | LKTQSGLDLQ | QRAGYTVQAE | RLNFLRFLSF | FRAVHRGASF |
| 490 | 500 | 510 | 520 | 530 | 540 |
| AGLRTTTVRK | LLPESWGFLC | PVHTPDGTPC | GLLNHMTRTS | RITSQFDSKG | NIRDFLKIRK |
| 550 | 560 | 570 | 580 | 590 | 600 |
| SVVDVLTGAG | MVPSLPKLVR | AGPPKVIHVL | LDGQVVGTLS | SNLVTKVVSY | IRRLKVEAPS |
| 610 | 620 | 630 | 640 | 650 | 660 |
| VIPEDLEVGY | VPTSMGGSYP | GLYLASCPAR | FIRPVKNISI | PSDNIELIGP | FEQVFMEISC |
| 670 | 680 | 690 | 700 | 710 | 720 |
| PDGGNGGRNN | SSLATHEEIH | PTGMISVVAN | LTPWSDHNQS | PRNMYQCQMA | KQTMAYSTQA |
| 730 | 740 | 750 | 760 | 770 | 780 |
| LQFRADQKIY | HLQTPQSPVV | RTKTYTTYSI | DENPTGTNAI | VAVLAHTGFD | MEDAMILNKS |
| 790 | 800 | 810 | 820 | 830 | 840 |
| SVERGMCHGQ | IYQTENIDLS | DQNSRFDSGS | KSFRRSTNKA | EHFRIDADGL | PSVGQKLYPD |
| 850 | 860 | 870 | 880 | 890 | 900 |
| EPYCSIYDEV | TNKTRHMKRK | GTDPVIVDFV | SVDMKSKKHP | QRANIRFRHA | RNPIIGDKFS |
| 910 | 920 | 930 | 940 | 950 | 960 |
| SRHGQKGVCS | QLWPDIDMPF | NGVTGMRPDL | IINPHAFPSR | MTIAMLLESI | AAKGGSLHGK |
| 970 | 980 | 990 | 1000 | 1010 | 1020 |
| FVDATPFRDA | VKKTNGEEES | KSSLLVDDLG | SMLKEKGFNH | YGTETLYSGY | LGVELKCEIF |
| 1030 | 1040 | 1050 | 1060 | 1070 | 1080 |
| MGPVYYQRLR | HMVSDKFQVR | STGQVDQLTH | QPIKGRKRGG | GIRFGEMERD | SLLAHGASYL |
| 1090 | 1100 | 1110 | 1120 | 1130 | 1140 |
| LHDRLHTSSD | HHIADVCSLC | GSLLTSSVVN | VQQKKLIQEI | GKLPPGRTPK | KVTCYSCKTS |
| 1150 | 1160 | 1170 | |||
| KGMETVAMPY | VFRYLAAELA | SMNIKMTLQL | SDREGVTD |