A6Q5J0
Gene name |
dapD |
Protein name |
2,3,4,5-tetrahydropyridine-2,6-dicarboxylate N-succinyltransferase |
Names |
Tetrahydrodipicolinate N-succinyltransferase, THDP succinyltransferase, THP succinyltransferase, Tetrahydropicolinate succinylase |
Species |
Nitratiruptor sp (strain SB155-2) |
KEGG Pathway |
nis:NIS_1643 |
EC number |
2.3.1.117: Transferring groups other than amino-acyl groups |
Protein Class |
|
Descriptions
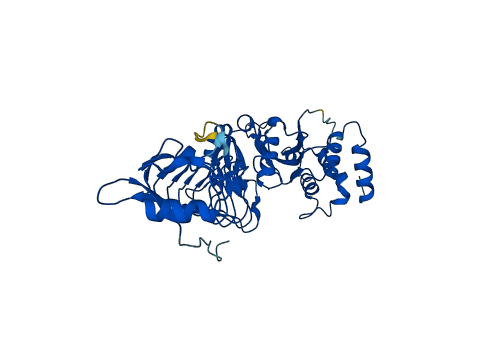
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
1 structures for A6Q5J0
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| AF-A6Q5J0-F1 | Predicted | AlphaFoldDB |
No variants for A6Q5J0
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
| No variants for A6Q5J0 | |||||
No associated diseases with A6Q5J0
Functions
| Description | ||
|---|---|---|
| EC Number | 2.3.1.117 | Transferring groups other than amino-acyl groups |
| Subcellular Localization |
|
|
| PANTHER Family | ||
| PANTHER Subfamily | ||
| PANTHER Protein Class | ||
| PANTHER Pathway Category | No pathway information available | |
1 GO annotations of cellular component
| Name | Definition |
|---|---|
| cytoplasm | The contents of a cell excluding the plasma membrane and nucleus, but including other subcellular structures. |
1 GO annotations of molecular function
| Name | Definition |
|---|---|
| 2,3,4,5-tetrahydropyridine-2,6-dicarboxylate N-succinyltransferase activity | Catalysis of the reaction: (S)-2,3,4,5-tetrahydrodipicolinate + H(2)O + succinyl-CoA = L-2-succinylamino-6-oxopimelate + CoA. |
2 GO annotations of biological process
| Name | Definition |
|---|---|
| diaminopimelate biosynthetic process | The chemical reactions and pathways resulting in the formation of diaminopimelate, both as an intermediate in lysine biosynthesis and as a component (as meso-diaminopimelate) of the peptidoglycan of Gram-negative bacterial cell walls. |
| lysine biosynthetic process via diaminopimelate | The chemical reactions and pathways resulting in the formation of lysine, via the intermediate diaminopimelate. |
No homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| No homologous proteins | ||||
| 10 | 20 | 30 | 40 | 50 | 60 |
| MIQTKDDFFA | LVNEIQSSAY | YKEPLAFGIA | RVDRGQKNPE | KILQATFPFI | NWKENYGSAA |
| 70 | 80 | 90 | 100 | 110 | 120 |
| IFQKALHETG | KLLNDESEAV | YDVTKNFVAE | ALSYCNPWIE | EAIGDAHKNV | QVIKYLSTLD |
| 130 | 140 | 150 | 160 | 170 | 180 |
| EEELANFKIV | FLFEDAAPKS | VEAVYLKLYA | LSTGKAALRS | VNLNGAFGIL | HNVAWSGTTP |
| 190 | 200 | 210 | 220 | 230 | 240 |
| IELDWLRENE | LELKMSGQYP | VIDSVDKFPR | FLQHIIPADN | TRILDAAKVR | MGAQLAAGTT |
| 250 | 260 | 270 | 280 | 290 | 300 |
| VMPGASYINF | NAGTLGPVMV | EGRISSSAVV | GKGSDVGGGA | SILGVLSGTS | GNPISIGENC |
| 310 | 320 | 330 | 340 | 350 | 360 |
| LLGANSVTGI | PLGNGCIVDA | GIAVLEGTKF | FMSEADYEKI | KEANPEWNAE | YKEFFKGREL |
| 370 | 380 | 390 | |||
| AGLSGLHFRQ | DSTSGQMKVF | RSNKEVKLNE | ELH |